An enterprise AI company building advanced medical conversational models for clinical and patient-facing applications.
Medical conversational AI cannot be trained on raw conversations alone. Each interaction must be clinically sound, logically structured, and medically safe.
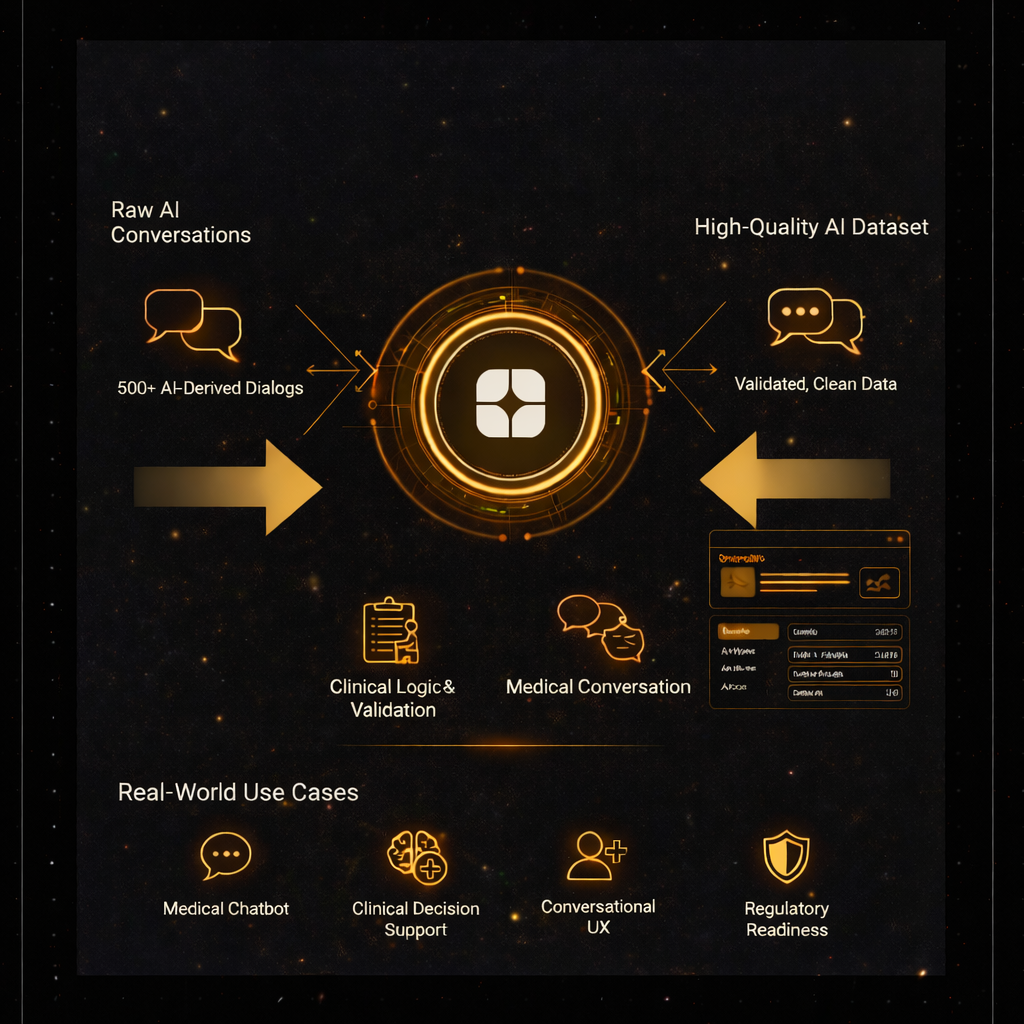
The client had generated over 500 AI-derived medical conversations, simulating doctor-patient interactions across a wide spectrum of medical conditions. These included both generic medical queries and specialized disease-focused discussions.
Before using this data for model training, the client needed expert clinical evaluation to determine whether each conversation was fit for purpose.
Key challenges included:
Automation alone was not sufficient. This task required medical judgment, not pattern matching.
Globik AI deployed a specialized panel of practicing doctors with experience across multiple medical domains to evaluate the conversations.
Each conversation underwent a structured review process that included:
The workflow was designed for speed without compromising clinical rigor, allowing doctors to focus purely on evaluation while Globik AI handled orchestration, quality checks, and consolidation.
All 500 medical conversations were evaluated and delivered within three working days, meeting the client’s urgency without sacrificing quality.
Outcomes included:
The client gained confidence that only clinically sound and contextually valid conversations were being used to train their medical AI systems.
In healthcare AI, accuracy is not enough. Conversations must be clinically responsible, logically consistent, and safe for real-world use.
By combining domain-specific medical expertise with a fast, structured evaluation process, Globik AI helped the client eliminate risk at the data layer, long before model deployment.
This project highlights Globik AI’s strength in executing expert-driven, high-stakes evaluations at speed, where the cost of poor data is exceptionally high.