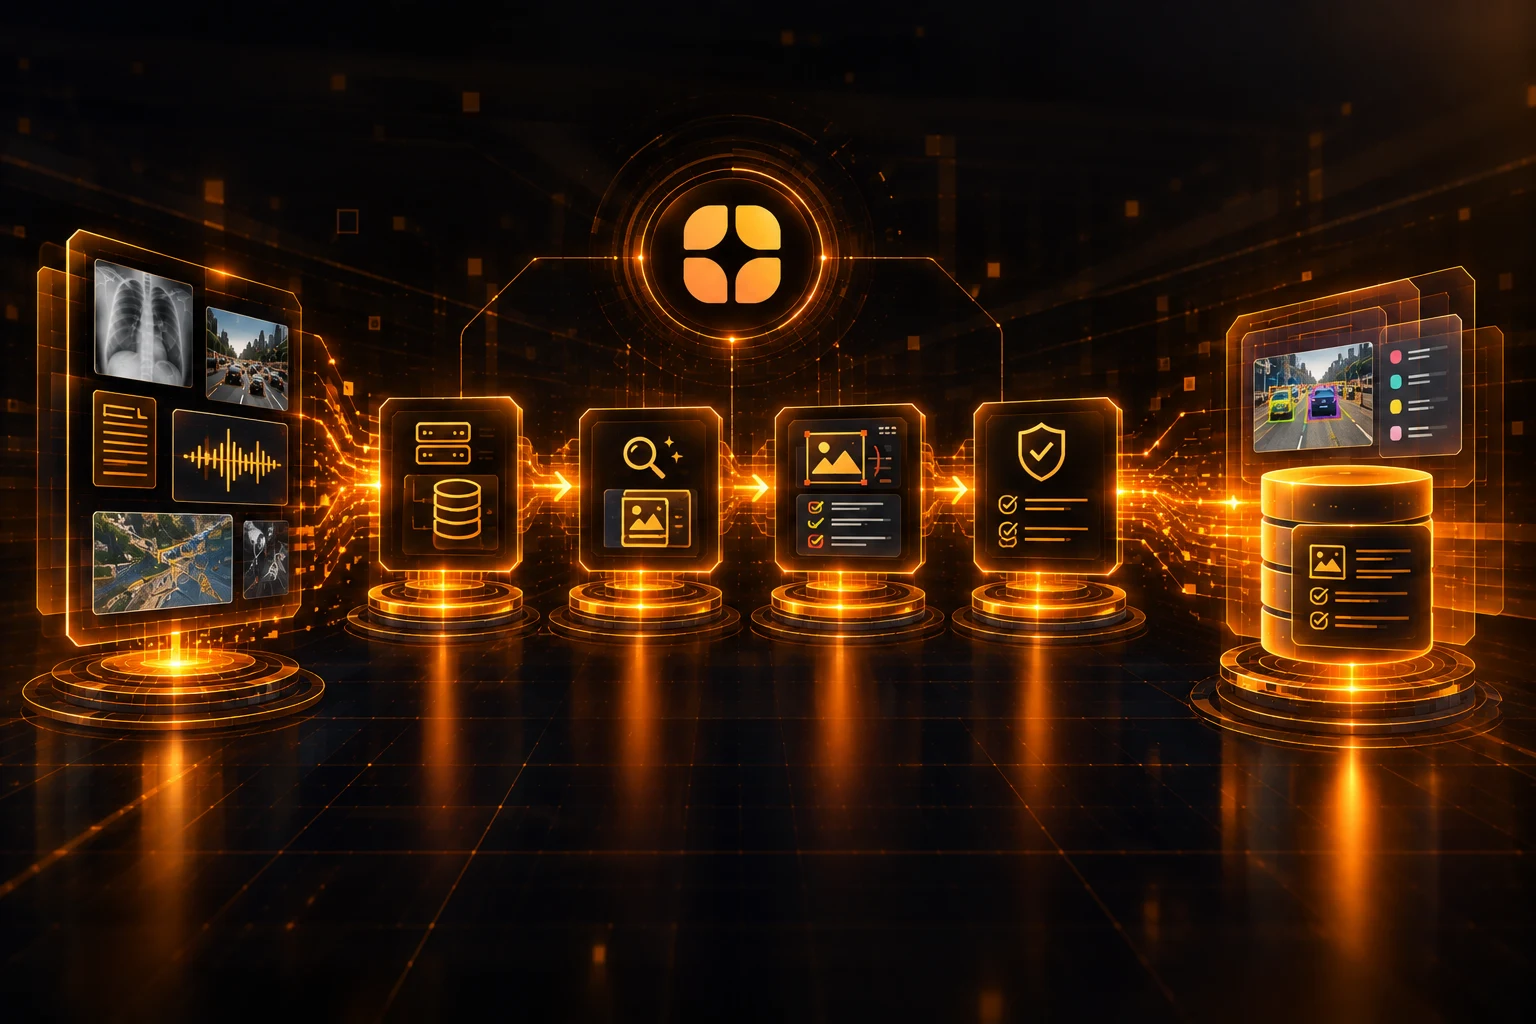
Training-ready data" gets treated in a lot of AI conversations as though it's simply a status a dataset arrives at once someone finishes labeling it. In reality, the distance between raw data, a folder of scraped images, an export of customer transcripts, a batch of sensor recordings, and a dataset genuinely ready to train a reliable model is a long, deliberate pipeline with several distinct stages, each capable of introducing quality problems if it's rushed or skipped. Understanding what actually happens in that pipeline matters enormously for anyone evaluating a vendor, planning an AI project timeline, or trying to figure out why a dataset that looked fine on delivery produced a model that underperformed once it hit production.
This post walks through the full pipeline, stage by stage, from the moment raw data arrives to the point where it's genuinely ready to train a model an organization can trust.
Before any labeling happens, data has to actually be gathered, and this stage shapes everything that follows more than it typically gets credit for.
Defining what data is actually needed. This starts with a clear specification of what the training data needs to represent, the range of scenarios, edge cases, and conditions a model will eventually need to handle, rather than simply collecting whatever data happens to be conveniently available.
Sourcing from appropriate, representative channels. Whether data comes from web scraping, internal systems, sensor capture, or synthetic generation, the sourcing method needs to actually reflect the diversity of real-world conditions the resulting model will face, not just the easiest or cheapest data to obtain.
Legal and licensing verification. Before any data enters a pipeline, it needs to be verified as legally usable for the intended purpose, respecting copyright, licensing terms, and, where personal data is involved, applicable privacy regulations.
Initial volume and coverage assessment. Even at this early stage, a rough assessment of whether the collected data covers the necessary range of scenarios in sufficient volume helps catch major gaps before investing further effort downstream.
Raw data is essentially never ready for annotation as-is, and skipping or rushing this stage creates problems that compound through every later step.
Deduplication. Removing duplicate or near-duplicate examples prevents a dataset from being artificially skewed toward whatever happened to be captured or scraped multiple times, which can otherwise distort a model's learned sense of what's typical.
Format standardization. Raw data often arrives in inconsistent formats, different file types, inconsistent resolutions, varying text encodings, and standardizing this is necessary before consistent annotation is even possible.
Filtering out low-quality or irrelevant content. This includes removing corrupted files, clearly irrelevant content that slipped into the collection process, and examples too degraded in quality to be usable, before annotator time gets spent on data that was never going to be usable anyway.
Initial anonymization or de-identification, where required. For data involving personal or sensitive information, appropriate anonymization needs to happen at this stage, before the data reaches annotators, not as an afterthought applied post-labeling.
Structuring for the annotation workflow. Data needs to be organized and formatted in a way that's actually compatible with the annotation tools and workflow that will be used, which often requires meaningful restructuring from however the data originally arrived.
Before annotation begins at scale, the specific rules and standards for labeling need to be developed and tested, a stage that's frequently under-invested in relative to how much it actually shapes final data quality.
Developing detailed, specific labeling guidelines. Vague or overly general guidelines are one of the most common sources of inconsistent annotation, and effective guidelines need to address the specific edge cases and ambiguities relevant to the actual task and domain.
Involving domain experts in guideline creation. For specialized tasks, domain experts need to be involved in defining guidelines from the outset, not brought in only for review after generalist-written guidelines are already in place.
Running a pilot batch before full-scale annotation. A small pilot batch, annotated and carefully reviewed, surfaces ambiguities and gaps in the guidelines before they propagate across an entire large-scale dataset, making this a genuinely high-leverage step relative to its cost.
Refining guidelines based on pilot results. Issues surfaced during the pilot, points of confusion, unanticipated edge cases, recurring disagreement, need to feed directly back into guideline revisions before scaling up annotation volume.
This is the stage most conversations about data annotation focus on almost exclusively, but as this pipeline overview makes clear, it's one part of a longer process, not the whole story.
Matching annotator expertise to task complexity. As covered extensively elsewhere, this means recruiting generalist annotators for straightforward tasks and genuinely qualified domain experts for tasks where specialized judgment is required.
Structured annotator training and calibration. Even well-qualified annotators need specific training on a project's particular guidelines and calibration exercises to align their judgment with the intended standard before labeling production data.
Systematic labeling at scale. This is the actual labeling work, applying the developed guidelines consistently across the full dataset, ideally supported by annotation tools designed for the specific data type and task involved.
Ongoing consistency monitoring during annotation. Rather than waiting until an entire dataset is complete, effective annotation processes monitor consistency, often through inter-annotator agreement metrics, throughout the annotation process, catching drift or emerging disagreement early enough to correct course.
Annotation on its own doesn't guarantee accuracy, which is why a distinct, structured quality assurance stage matters as much as annotation itself.
Automated structural and statistical checks. This includes format validation, outlier detection, and statistical consistency checks that can efficiently catch a meaningful share of errors before more expensive human review is needed.
Expert review of flagged and sampled examples. Domain-qualified reviewers examine examples flagged by automated checks, along with a structured sample of the broader dataset, to catch nuanced errors that automated systems can't evaluate.
Adjudication of disagreements. Where annotators disagree, particularly on genuinely ambiguous cases, a defined adjudication process resolves the disagreement and documents the reasoning, feeding back into guideline refinement where recurring patterns emerge.
Dataset-level distribution and bias checks. Beyond individual example review, this stage evaluates whether the overall dataset's label distribution looks reasonable and representative, catching systemic issues that wouldn't be visible from reviewing individual examples alone.
Outcome verification, where feasible. For datasets where downstream outcomes can eventually be confirmed, this stage connects labeled examples back to real-world verified results wherever the data and timeline allow it.
Even fully validated, accurately labeled data still needs a final stage of preparation before it's genuinely ready to train a model.
Structuring data into the required training format. Different model architectures and training frameworks expect data in specific formats, and this stage converts validated, labeled data into whatever structure the intended training pipeline actually requires.
Train, validation, and test set splitting. Data needs to be deliberately divided into appropriately sized and representative subsets for training, validation during development, and final held-out testing, done carefully enough to avoid data leakage between these sets.
Final documentation and metadata compilation. This includes documenting exactly how the data was collected, annotated, and validated, providing the traceability that regulated industries in particular increasingly require, and that any team should want regardless of regulatory pressure.
Final volume and coverage verification. A last check confirms the delivered dataset actually meets the volume and coverage requirements established at the start of the project, catching any gaps before the data moves into actual model training.
Each stage in this pipeline exists specifically to catch a category of problem that the other stages don't reliably catch on their own. Skipping data cleaning means annotators waste time on unusable content and potentially introduce noise from duplicated or corrupted examples. Skipping pilot testing means guideline ambiguities get discovered only after they've already propagated across a large-scale dataset, requiring expensive rework. Skipping structured quality assurance means annotation errors, however well-intentioned the annotators were, make it directly into a model's training data undetected. Skipping careful formatting and splitting can introduce data leakage that makes a model's evaluation results look artificially strong.
This is why treating "annotation" as synonymous with "getting training-ready data" undersells how much work, and how many distinct opportunities for quality control, actually sit around that central labeling step. A dataset that looks complete after annotation but skipped rigorous cleaning, piloting, or quality assurance is not actually training-ready, even though it may appear to be on a quick surface review.
Budget time and resources for every stage, not just annotation itself. Cleaning, guideline development, piloting, quality assurance, and formatting each require real time and expertise, and compressing a project timeline by skipping these stages tends to produce data that looks finished but isn't genuinely reliable.
Ask vendors to walk through their full pipeline, not just their annotation process. A vendor's answer to "how do you clean and validate data before and after annotation" reveals a lot more about likely data quality than their answer to "how do you label data" alone.
Invest specifically in the pilot testing stage. This is one of the highest-leverage, lowest-cost stages in the entire pipeline, and skipping it to save time upfront frequently costs considerably more in downstream rework.
Treat quality assurance as a distinct stage with its own dedicated process, not an informal step folded into annotation itself, given how much a separate, structured QA process catches that annotation alone doesn't.
The distance between raw data and genuinely training-ready data spans a long, deliberate pipeline: collection and sourcing, cleaning and preprocessing, guideline development and piloting, annotation itself, structured quality assurance, and final formatting and delivery preparation. Each stage exists to catch specific problems the others don't, and treating any one of them, especially annotation, as the entire process undersells how much careful work actually determines whether a dataset can be trusted to train a reliable model.
For organizations planning AI data projects, understanding this full pipeline, and insisting on genuine rigor at every stage rather than just the labeling step, is what actually separates data that's truly training-ready from data that merely looks finished.
It means data that has been collected, cleaned, accurately labeled according to well-tested guidelines, validated through structured quality assurance, and properly formatted and split for training, not simply data that has been through a labeling process.
Because raw data often contains duplicates, inconsistent formats, corrupted or irrelevant content, and unaddressed privacy considerations, all of which need to be resolved before annotator time is spent labeling data that may not even be usable.
Pilot testing involves annotating and carefully reviewing a small batch of data before scaling up to the full dataset, surfacing ambiguities and gaps in labeling guidelines early, before they propagate across a much larger volume of data.
Because annotation, even when done carefully, doesn't guarantee accuracy on its own. A distinct quality assurance stage, including automated checks, expert review, and disagreement adjudication, is needed to catch errors that annotation alone doesn't reliably prevent.
This stage includes automated structural and statistical checks, expert review of flagged and sampled examples, adjudication of annotator disagreements, dataset-level bias and distribution checks, and outcome verification where feasible.