Most teams treat annotation guidelines as paperwork. Write them once, drop them in a shared drive, move on to the actual work.
That's the first mistake in the pipeline and it's usually the one that costs the most later.
A guideline written as a document assumes the world holds still. It assumes every edge case was anticipated on day one. It assumes annotators read page 14 as carefully as page 1.
None of that is true.
Real data is messy. Real taxonomies evolve. Real annotators even excellent ones interpret ambiguous instructions differently, especially at scale, especially under deadline pressure. A static PDF can't answer a question it didn't anticipate. It can't be updated mid-batch without breaking consistency between annotator A on Monday and annotator B on Friday. It can't tell you, six weeks later, which rule actually shaped your model's behavior.
That's not a documentation problem. It's a design problem.
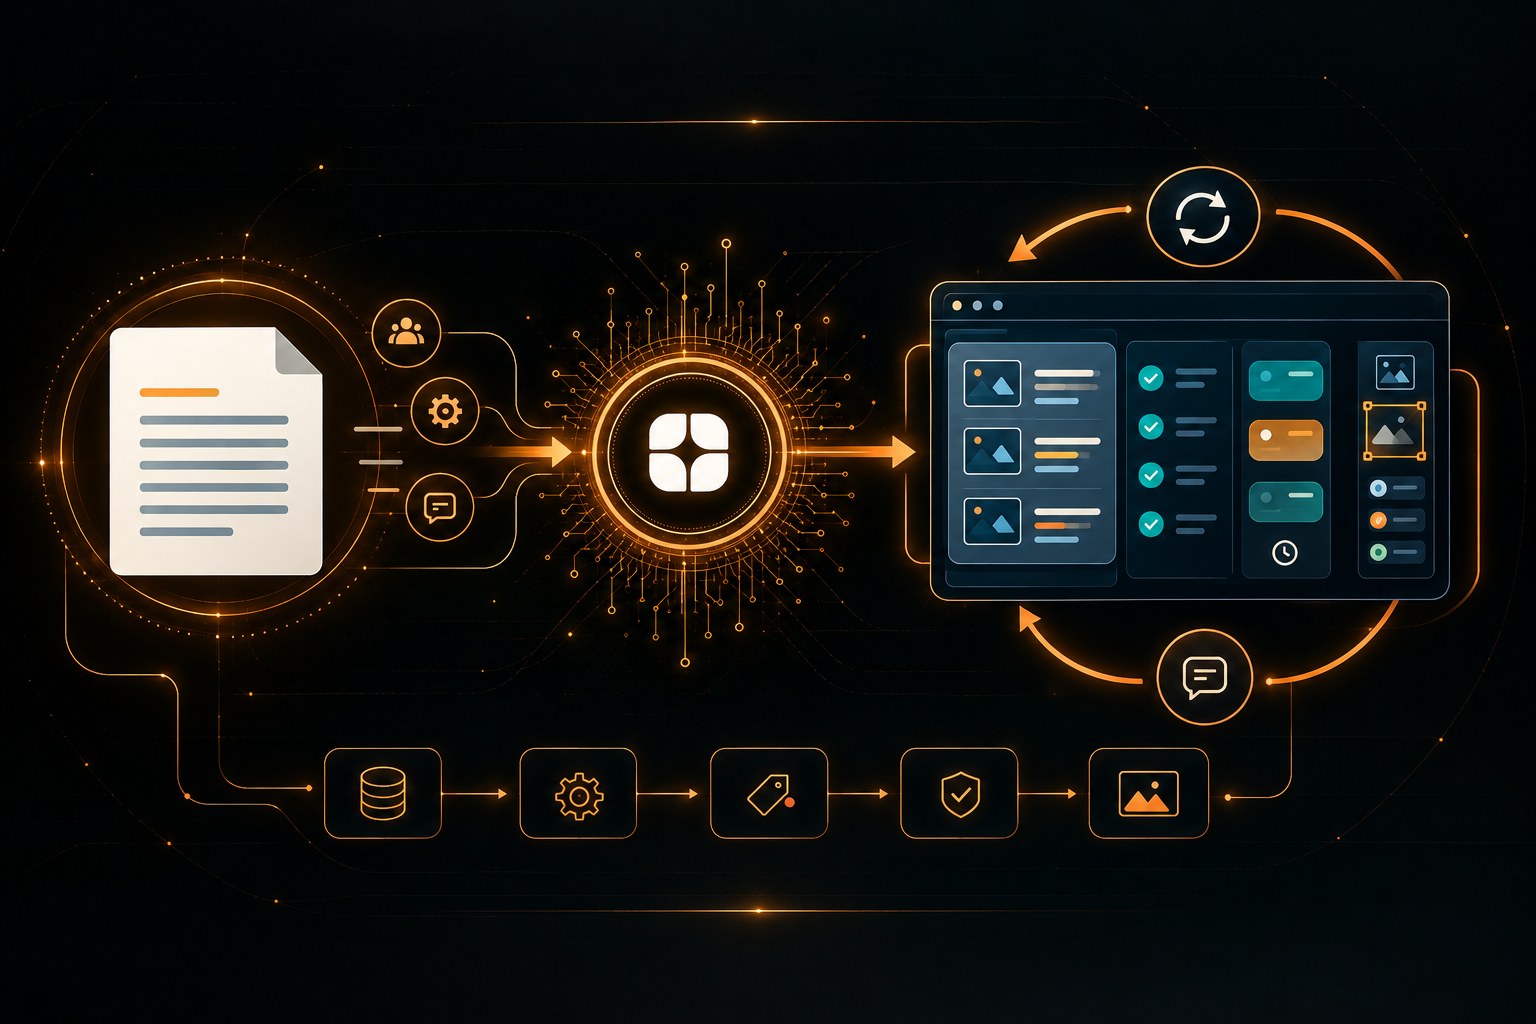
A product has a spec, a version history, an owner, and a feedback loop. Annotation guidelines need all four.
Guidelines aren't a formality sitting upstream of the "real" work. They are the work. Every ambiguity left unresolved in the instructions becomes inconsistency in the labels and inconsistency in the labels becomes a ceiling on what your model can learn, no matter how sophisticated the architecture downstream.
This is where data pipeline design and annotation guidelines stop being separate concerns. A pipeline built for scale but not for guideline rigor just produces inconsistent data faster.
At Globik, this shows up as structural, not aspirational:
This is also why generic, crowdsourced annotation marketplaces struggle here. Guidelines-as-product only works with continuity: the same reviewers, the same domain expertise, the same accountable pipeline from batch one to batch one hundred. A rotating pool of anonymous, task-based contributors can execute a static instruction sheet. They can't maintain a living spec.
You don't need a full platform rebuild to start applying this mindset. Most teams can shift from static documents to living guidelines in four steps.
1. Audit your current guideline for ambiguity. Pull a sample of labeled data and check for disagreement patterns. Wherever two annotators interpreted the same rule differently, that's a gap in the spec, not a training issue.
2. Assign an owner, not a committee. Guidelines drift when no one is accountable for them. Name one person responsible for approving changes, resolving disputes, and keeping the document current the same way a product owns a backlog.
3. Build in a lightweight version log. It doesn't need to be complex. A simple changelog what changed, why, and which batch it applies from is enough to prevent silent inconsistency between old and new labeled data.
4. Create a feedback channel from annotators back to the spec. If annotators can only follow instructions and never flag what's missing, the guideline stays frozen in its first draft. Even a simple weekly log of edge cases resolved and forwarded to the guideline owner closes the loop.
None of this requires new tooling on day one. It requires deciding that the guideline is a living asset and treating it that way from the next batch onward.
If your annotation guidelines haven't changed since you wrote them, that's not a sign of stability it's a sign no one's using the feedback loop. Guidelines that work are versioned, owned, tested, and revised, the same way any product roadmap is.
Treat the instructions with the same rigor you'd expect from the model they're training. The data pipeline is only as good as the spec sitting at the top of it.
Treating annotation guidelines as a product means managing them like a software feature: with a defined spec, version history, a single accountable owner, and a continuous feedback loop from annotators. This replaces the common practice of writing a static document once and never revisiting it.
Annotation guidelines need version control because labeling rules change as new edge cases appear, and without tracking those changes, teams can't tell which data batches were labeled under an old rule versus a new one. This creates hidden inconsistency in the training data.
No, high inter-annotator agreement only shows that annotators are consistent with each other, not that their labels are accurate. In specialized fields like healthcare, legal, or finance, catching mislabeled-but-consistent data requires review by a subject matter expert, not just an agreement score.
Annotation guidelines affect model performance because any ambiguity left unresolved in the instructions becomes inconsistency in the labeled data, and inconsistent data creates a ceiling on how well a model can learn — regardless of how advanced the model architecture is.
A single accountable owner should maintain annotation guidelines, similar to how a product manager owns a feature roadmap. This person resolves ambiguity, incorporates feedback from annotators, and keeps the guidelines updated, rather than leaving decisions to informal team knowledge.
A team can start treating annotation guidelines as a product by auditing existing labeled data for disagreement patterns, assigning one accountable owner, maintaining a simple version log of changes, and creating a feedback channel for annotators to flag missing edge cases. These four steps require no new tooling and can begin with the very next labeling batch.