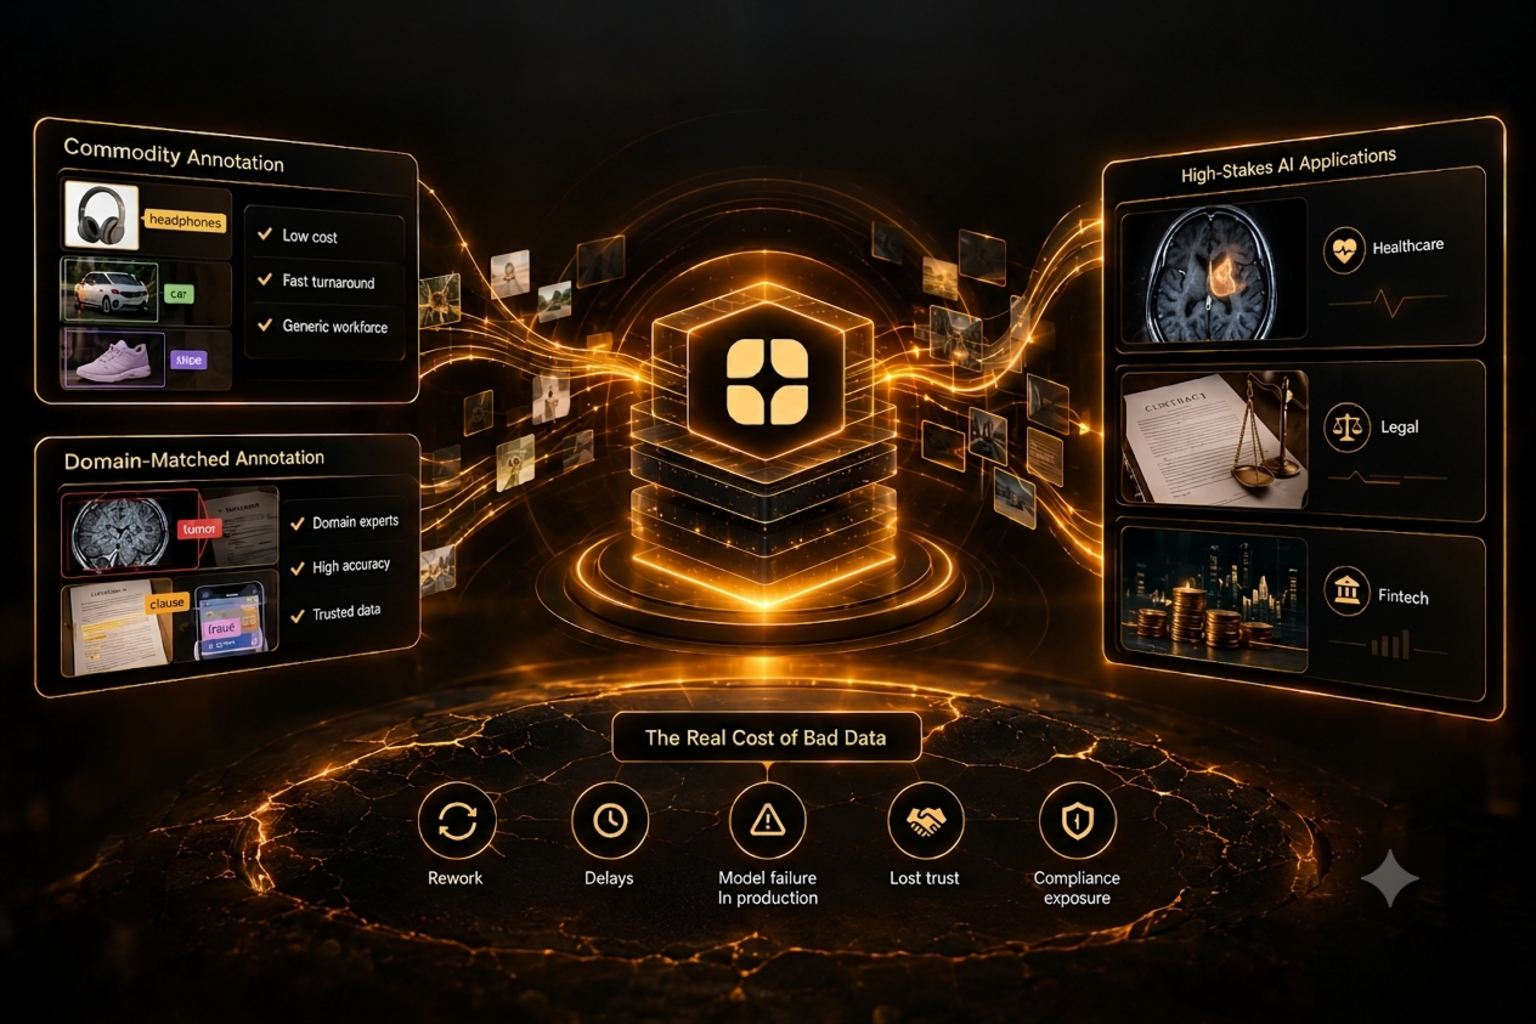
Commodity annotation is sold on a simple promise: lower price per label, faster turnaround, done. For a chatbot that recommends movies or a model that sorts product photos, that trade-off can be perfectly reasonable. But when the AI system reads an MRI, flags a contract clause, or approves a loan, the price per label is the smallest number in the equation. The real cost of bad data shows up later, in places a procurement spreadsheet never looks.
This post walks through what commodity annotation actually costs once a high-stakes model is built on it, and why data labeling ROI has to be measured over the life of the model, not at the invoice stage.
In a low-stakes system, a wrong label mostly costs you a slightly worse recommendation. In a high-stakes system, a wrong label can cost you a wrong diagnosis, a missed legal obligation, or a credit decision you can't explain to a regulator.
Three things make high-stakes AI different:
When a team chooses the lowest-cost labeling option for a high-stakes project, the real bill tends to arrive in five parts.
None of these five costs appear on a vendor's price sheet. They appear months later, in engineering time, legal review, or a client relationship that has to be rebuilt. By the time a team adds up the hours spent on rework, the revenue lost to a delayed launch, and the engineering time spent tracing a production failure back to its root cause, the "savings" from choosing the cheapest labeling option have usually disappeared several times over.
The risk of AI model failure from weak labeling is not evenly spread. It concentrates wherever domain judgment matters more than pattern recognition.
Healthcare: Annotating a radiology scan or a pathology slide requires someone who can recognize what a finding actually means, not just trace a shape around it. A generalist annotator can draw a technically correct bounding box around the wrong structure, and that error can propagate into a diagnostic model.
Legal: Contract and compliance data is full of language that looks ordinary but carries specific legal weight. Someone without legal training can easily misclassify a clause, and a model trained on that mistake will keep making the same misclassification at scale.
Fintech: Labeling transaction data, fraud signals, or credit documents requires understanding regulatory categories that are not obvious from the text alone. A labeling error here does not just reduce accuracy; it can bias a lending or risk model in ways that are difficult to detect and expensive to unwind.
A cheaper label is not a better return if it has to be redone, if it delays launch, or if it ends up inside a model that fails in front of a client. Real data labeling ROI has to account for the full lifecycle of the data, not just the cost per item.
That means asking a different set of questions before a project starts:
These questions matter more in high-stakes AI than anywhere else, because the downstream cost of getting them wrong is so much higher. A team that asks them upfront, before a contract is signed, is far more likely to catch a quality gap while it is still cheap to fix, rather than after it has already shaped months of model training.
Globik AI is built around the idea that high-stakes data needs verified judgment, not volume. Every expert who touches a project goes through identity and background checks, an AI-led interview, a domain assessment, and reference checks, so the person labeling a radiology image or a loan document is qualified to understand it, not just annotate it.
This is also why every engagement starts small. A 30-minute discovery call maps the domain and the quality bar. Expert match follows in 2 to 5 days, pulling specialists from a verified network rather than an open crowd. A scoped phase of 1 to 2 weeks then runs a small, real slice of the work end to end, so the quality is visible before any long-term commitment is made. We've written before about the hidden costs of crowd-sourced annotation at enterprise scale, and the same pattern holds here: the risk is not that commodity labeling is always wrong; it is that nobody can tell the difference between right and wrong until the damage is already in production.
The cheapest label and the most expensive label can look identical on day one. The difference only shows up once the model is in front of real patients, real contracts, or real credit decisions. For high-stakes AI, the question worth asking before a project starts is not "what does this cost per label," but "what does it cost if this label is wrong." If you want a clear view of where your current labeling approach stands, a 30-minute scoping call is a low-risk place to start.
Commodity annotation is built for speed and low cost, not domain understanding. In healthcare, legal, or fintech AI, a label that looks correct but misses the underlying meaning can directly shape a diagnosis, a legal interpretation, or a credit decision, making the cost of a mistake far higher than in low-stakes use cases.
Data labeling ROI in high-stakes AI has to include rework, delayed launches, in-production model failures, and compliance exposure, not just the price per label. A cheaper label that has to be redone or that causes a downstream failure is not actually a better return.
It rarely looks dramatic. A model trained on shallow or inconsistent labels tends to perform reasonably well on easy cases and fail quietly on the harder, less common edge cases, which are often the exact cases that matter most in healthcare, legal, and fintech settings.
Because the judgment required to label the data correctly is the same judgment the model is later expected to replicate. A fast but shallow label teaches the model the wrong pattern, and that pattern is expensive to find and correct once the model is deployed.
By asking whether annotators are verified for domain knowledge, whether there is a clear record of who labeled what, and whether QA checks for domain correctness rather than just formatting. A short-scoped project, run end to end on a real sample of data, is usually the fastest way to see the actual quality level.