Crowd-sourced annotation looks like a bargain. You upload your data, thousands of people label it, and the price per label is low. For a small test project, this can feel like a smart move.
But at enterprise scale, the picture changes. The real crowd annotation risk does not show up on the invoice. It shows up later, in model errors, rework, and lost trust. This post explains where those hidden costs come from and how to avoid them.
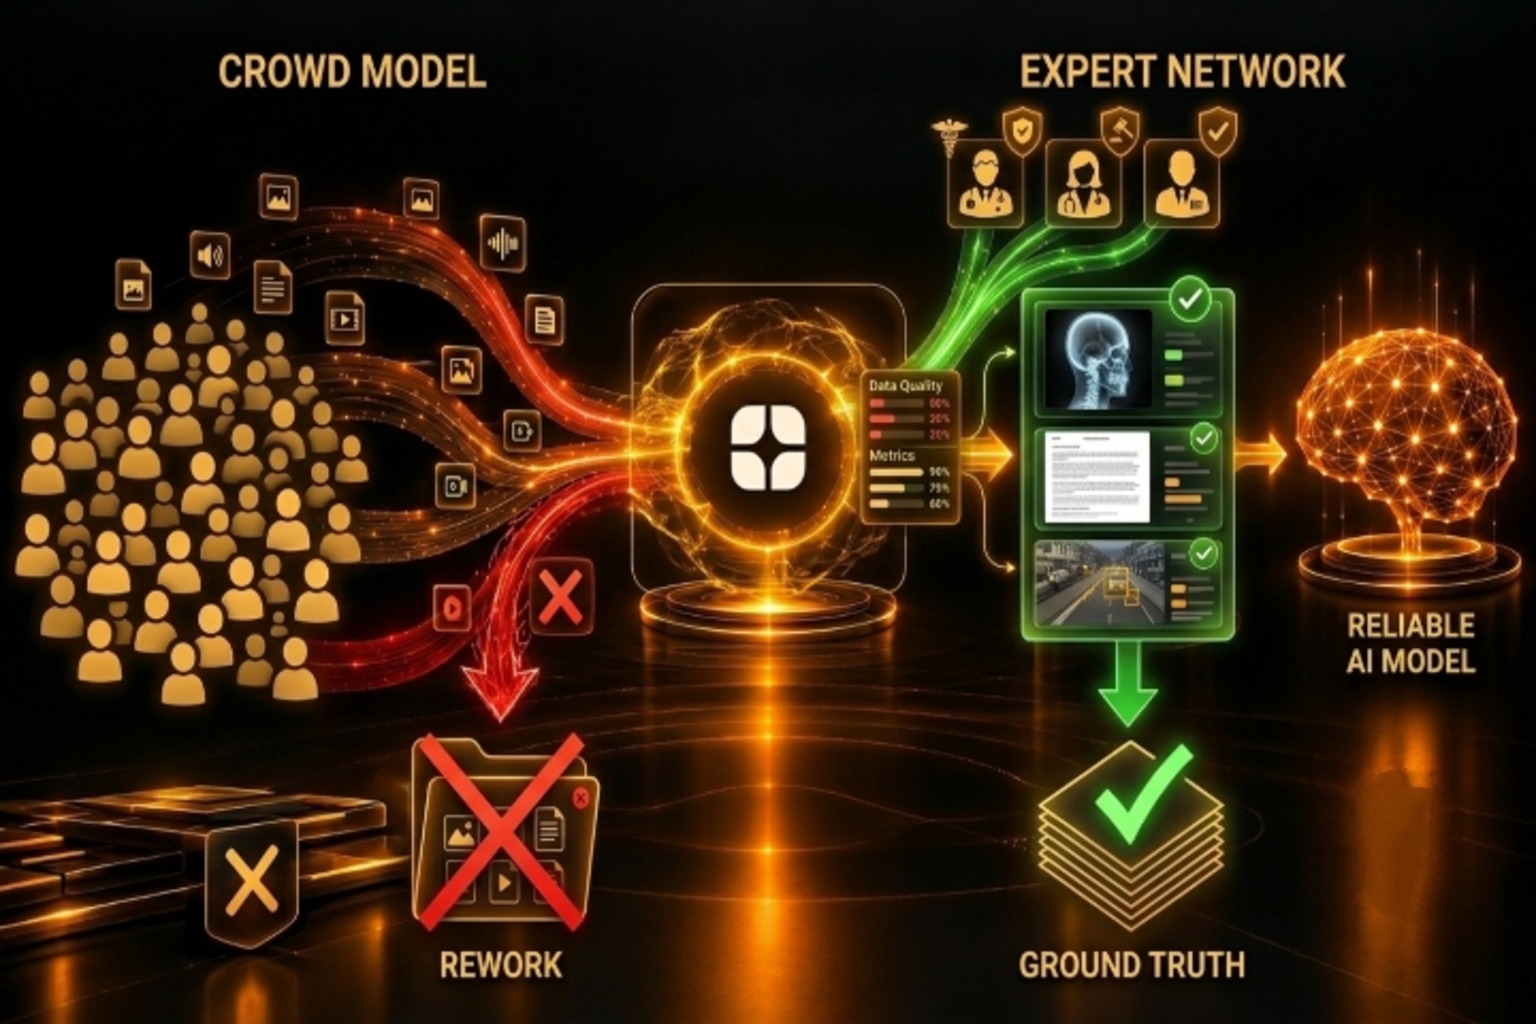
Crowd-sourced annotation means sending labeling tasks to a large, open pool of workers. Anyone who signs up and passes a basic test can take part. The goal is volume and speed, and the model works well for simple tasks with clear answers.
The trouble starts when the data is complex. A radiologist annotates medical data. A legal professional labels contracts. A native speaker handles multilingual voice data. Generic crowd workers do not. That gap is where most of the hidden cost lives.
Teams often find these problems only after they have scaled up.
Each of these costs more than the savings on the price per label.
The biggest driver of risk is simple: unverified annotators. If you do not know who labeled your data, you cannot know how much to trust it.
Think about what is missing when there is no vetting:
For low-stakes tasks, this may be acceptable. For healthcare, legal, fintech, and other high-stakes areas, it is a serious gap. You can read more about this in our post on the real cost of commodity labeling in high-stakes AI.
At a small scale, a few bad labels are easy to spot. At enterprise scale, the same problem grows quietly.
When you label millions of items, small error rates add up to a large number of bad examples. Review becomes harder, because no team can check everything by hand. And if the workforce keeps changing, the quality can change with it.
This is why data quality at scale needs more than a bigger crowd. It needs a trusted workforce, workflows built for your field, and several layers of quality checks. Adding more people to a weak process does not fix it. It only makes the problem bigger.
Globik AI takes a different path. We are not a crowd platform and not a commodity vendor. Crowd platforms chase volume. We chase ground truth, through verified domain experts, transparent workflows, and end-to-end accountability.
Here is what that means in practice:
Our network covers 20+ expert domains and 40+ languages. To see how this works in real work, read our case study on high-precision review and filtering of complex human semantic segmentation data, where we reviewed 7,500+ images with 50+ attributes.
You should not have to take quality on trust. That is why every Globik AI engagement starts small:
You see production quality on a small batch first. No long-term contracts are required.
Ask any annotation vendor these questions:
If the answers are unclear, you may be facing the same hidden costs described above. If you want a clear view of your options, start with a 30-minute call. No deck, no pitch, just scope. You can also see the full range of data annotation services we offer.
A. Crowd annotation risk is the chance that data labeled by an open, unvetted crowd is inaccurate, inconsistent, or lacks domain knowledge. These flaws can lead to weak models, rework, and delays. The risk grows as projects scale and as the data becomes more complex.
A. Unverified annotators have not been checked for identity, credentials, or domain skills. You cannot audit who labeled your data or trust that they understood it. This is especially risky in high-stakes areas like healthcare, legal, and fintech.
A. At scale, small error rates turn into a large number of bad examples, and manual review cannot catch them all. Data quality at scale needs a trusted workforce, domain-aligned workflows, and multi-layer QA, not just more workers.
A. It can work for simple, low-stakes tasks with clear rules. For complex or regulated data, a verified expert network is usually the safer choice because it brings domain knowledge and accountability.
A. Ask for a scoped phase. At Globik AI, a small, real slice of your data runs end to end in 1 to 2 weeks, so you can judge quality before you scale.
A. Every expert goes through identity and background checks, domain assessment, an AI-led interview, and reference checks before working on a project. Each expert is auditable.