Most talk about RLHF is about the model: the reward signal, the fine-tuning step, the behavior that comes out. Far less is said about the people at the start of the pipeline. They compare outputs, write examples, and decide what counts as unsafe. The whole technique runs on their judgment. If that judgment is thin, the AI training that follows is built on thin ground.
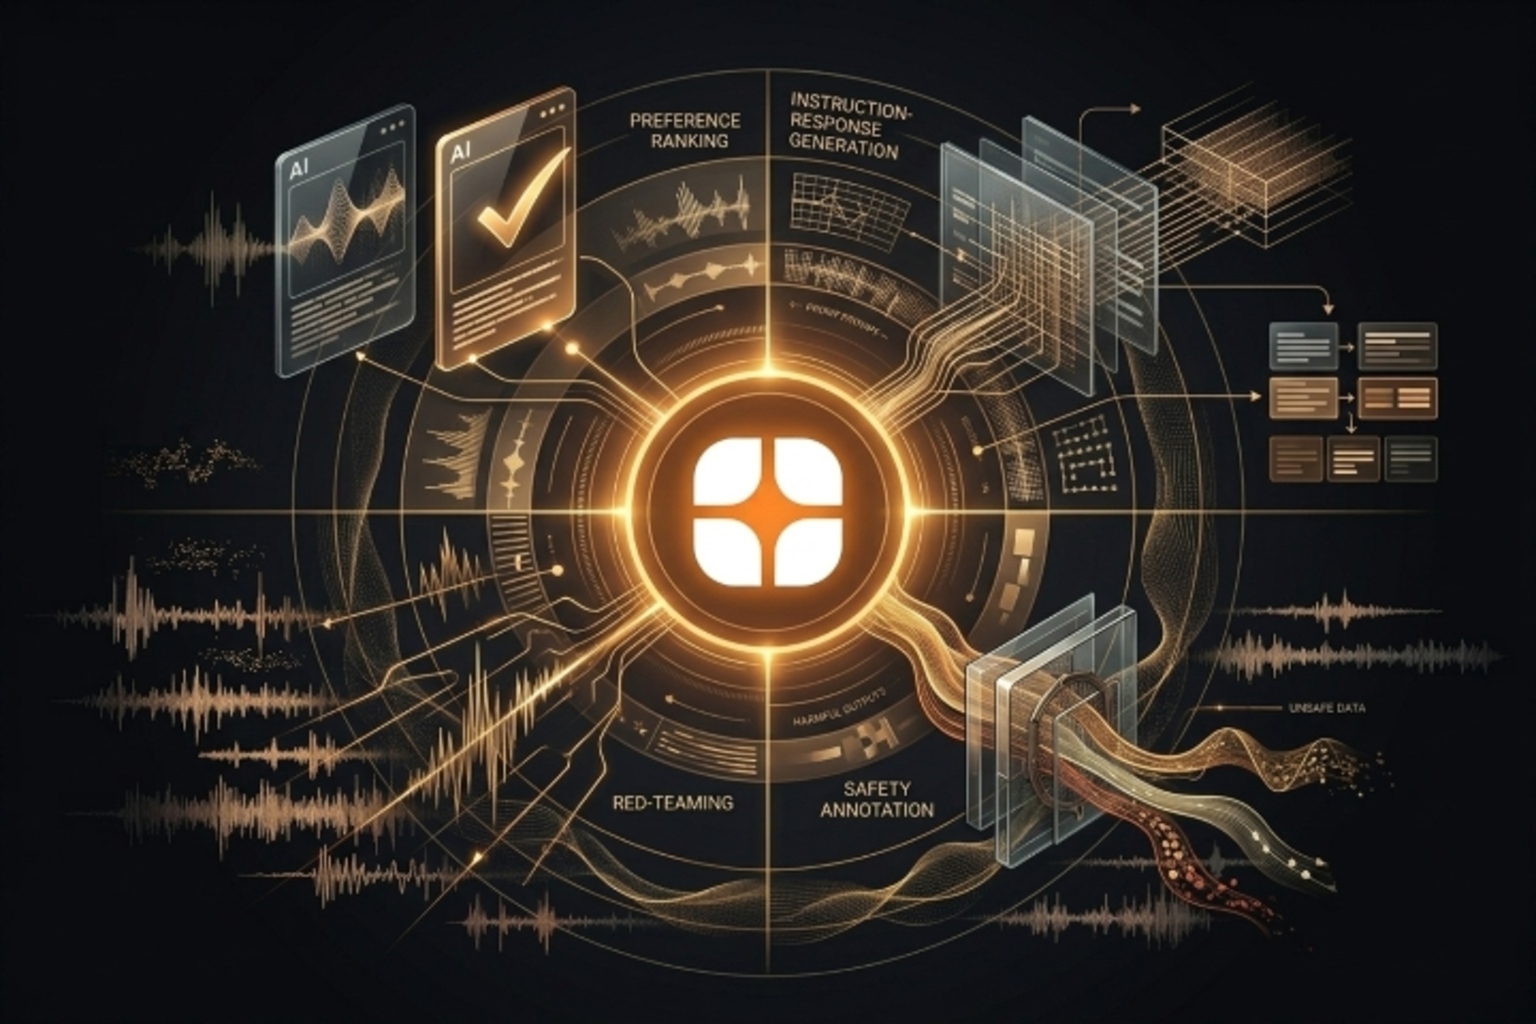
Globik AI's view of generative AI is direct: LLM quality comes down to the quality of its human feedback data. This post breaks that idea into four RLHF jobs and explains why each depends on who does it.
RLHF is often described as one step. People compare model answers, and those choices teach the model which outputs to favor. That is a fair summary, but it leaves out most of the work.
A real RLHF pipeline needs several kinds of human feedback, and each asks for something different. Treating them as one task makes it easy to staff them all the same way, usually with whoever is easiest to find. That is where quality starts to slip, because the person who suits one job may not suit another.
In preference ranking, a person looks at two or more model responses and decides which is better. Those choices become reward model data, the preference signal used to steer a model toward answers people favor.
Globik AI delivers this as RLHF preference dataset creation with domain-matched annotators. The key word is domain-matched. A ranking is only as reliable as the ranker's understanding of the subject. A legal answer should be judged by someone who knows the law, and a clinical answer by someone who knows medicine.
Before a model learns what people prefer, it needs examples of what a good answer looks like. Instruction-response pair generation means writing realistic instructions along with strong, correct responses, and doing it at scale.
Because these pairs show the model what "good" means, the writer's knowledge sets the ceiling. Instruction tuning needs annotators who understand the domain the model will serve.
Safety annotation means reviewing model outputs and classifying the ones that are harmful or unsafe. This work is about judgment, not just spotting obvious problems. Deciding whether an output is harmful, and why, depends on the context it appears in. That is why this job also needs annotators who understand the field the model is meant to serve.
Red-teaming data generation means creating test cases that deliberately try to make a model fail, so weak points show up before real users find them. Globik AI describes this as red-teaming data generation for adversarial AI testing.
It is the job most unlike the other three. Instead of judging answers, the person is trying to break them. The quality of the test cases depends on how well that person understands both the domain and the ways a model could go wrong.
Globik AI's website makes a pointed observation: most RLHF vendors use general populations for preference labeling. General raters are easier to find and quicker to start, and for broad tasks that can be enough.
The trouble comes in domain-grounded work. Instruction tuning, preference ranking, and safety annotation all call for annotators who understand the domain the model will serve. When they do not, the human feedback can look complete while pointing the model in the wrong direction. RLHF data quality is also one of the main differences between foundation models that perform reliably in production and those that do not, so it is not a place to save effort.
Globik AI is built around a simple principle: domain first. Instead of a crowd, the work goes to verified experts. Every expert goes through identity and background checks, a domain assessment, an AI-led interview, and reference checks, so every expert is auditable. For a deeper look at what that verification means, read our post on what "domain expert" actually means in data annotation.
Around the experts sits the delivery process. Work arrives in structured batches with multi-layer QA; you get weekly reporting, and each workstream has a named lead. That means the human feedback behind your RLHF project has a clear owner, and quality is checked at more than one point.
With general raters, the pool is wide and quick to start, but nothing guarantees that anyone understands the field the model will serve. With domain-matched experts, each person is verified, auditable, and matched to the subject. For simple, broad comparisons, the first approach can work. For instruction tuning, preference ranking, and safety annotation in a specialized field, the second is closer to what the work asks for.
If you are choosing a partner for AI training data, a few questions help:
You can see the full range of work, including RLHF and instruction tuning data, on our services page, or reach the team through the contact page. For where this field is heading, read our post on how RLHF is expanding beyond chatbots.
Every engagement begins with a scoped phase of one to two weeks, where a small slice of your work runs end to end, so you can judge the quality of the feedback before you scale. No long-term contract is required.
A. RLHF, or reinforcement learning from human feedback, is a method of AI training where people judge a model's outputs and that judgment is used to guide the model toward better behavior. The quality of the people giving feedback directly shapes the quality of the data, and so the quality of the model.
A.Reward model data is the human preference data used to teach a reward model what people favor. In practice, it usually comes from people ranking or comparing model responses. Because the model learns from these judgments, the knowledge and consistency of the people ranking them matters a great deal.
A. Domain knowledge matters because instruction tuning, preference ranking, and safety annotation all depend on annotators who understand the subject the model will serve. Someone unfamiliar with the field may not spot an answer that looks right but is wrong, so the human feedback can point the model in the wrong direction.
A. Globik AI's RLHF work covers four jobs: preference dataset creation with domain-matched annotators, instruction-response pair generation, safety annotation with harmful output classification, and red-teaming data generation for adversarial testing. Each job asks for a different kind of judgment from the person doing it.
A. Globik AI verifies every expert through identity and background checks, a domain assessment, an AI-led interview, and reference checks. The goal is that every expert is auditable, so you know who is giving the feedback that shapes your model, instead of an anonymous crowd.
A. Start with a scoped phase of one to two weeks, where a small slice of your work runs end to end, covering the rubric, annotation, QA, and delivery. You can judge the quality of the feedback and the communication before committing more volume. No long-term contract is required.