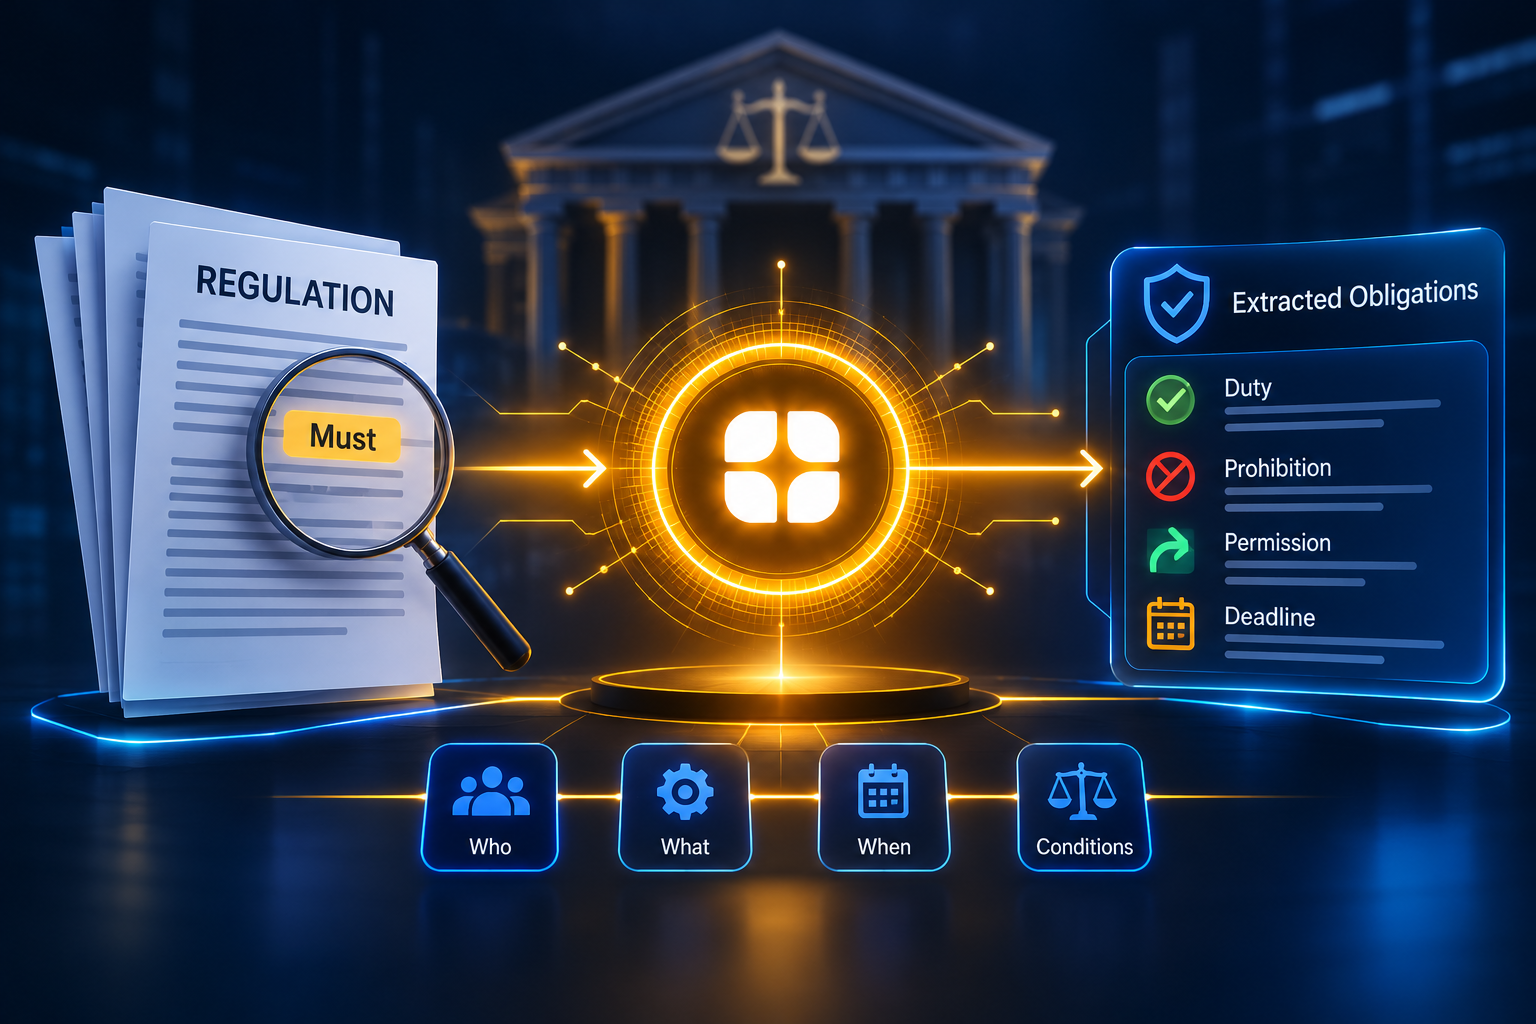
Rules are written for readers, not for software. A single regulation may run for hundreds of pages, and the duties inside it are tucked into long sentences, exceptions, and cross-references. Compliance teams must turn that text into a list of things the organization has to do, and check that each one is met.
AI can help, but only if it learns from carefully labeled examples. Good regulatory obligation extraction means finding each duty in the text and recording it in a form that can be checked, the same way every time. This post explains what the work covers, why it is hard, and what legal AI training data needs to get right.
Annotation for rule text usually has five parts:
Models trained on these labels can build a requirement checklist from new rules, flag what changed between versions, and help teams map each duty to an internal control.
Legal drafting is precise, but it is not simple. A reader who knows the language can still miss a duty buried in a long clause.
Annotators need written rules for each of these. The guide should define each type of statement, say whether a “should” is a duty or advice, and mark recitals and notes as non-operative. Without this, two people pull a different list of duties from the same page, and the model learns the disagreement. This is compliance text labeling where precision matters most.
Finding duties is about detection. Labelers scan the text and mark every sentence that creates a requirement. Errors come from missed duties inside long sentences and from marking background text as binding. Structuring duties is about breaking each one into parts: who, what, when, and under what condition. Errors come from wrong subjects, lost exceptions, and conditions attached to the wrong duty.
A single guide for both would blur these differences. Each needs its own definitions, examples, and reviewers.
A useful requirement can be tested. “Keep records appropriately” is hard to check, while “keep records for a stated period” is easier. Annotators should capture the actor, the action, the object, the condition, and the time limit. When one sentence holds several duties, each should be split into its own record, so a compliance team can track them separately.
Where the rule text is vague, a flag such as “needs interpretation” is more honest than forcing a precise-looking requirement. These items go to a specialist.
Link each exception to the duty it limits, not as a separate requirement. When a clause points to a definition or another section, record the target so the full meaning can be rebuilt. Each record should carry the version, effective date, and jurisdiction, since mixing versions gives the model contradicting rules.
Most sentences in a regulation do not create a duty. Include several rule types, such as reporting duties, bans, and deadlines, from different sectors and drafting styles, and collect more of the thin ones early. Keep all text from one regulation and its amendments on one side of the train and test split, or scores will look better than they are. Testing on a regulation the model has never seen gives the most honest result.
Some passages cannot support a clean label. Give annotators an “unclear” option and send doubtful cases to a legal reviewer. A missed duty and an invented duty both cause harm, so the rules should say how each is handled. Our guide to patent claim and prior art annotation covers a related need to break precise legal text into parts and tie each label to evidence.
People with legal and compliance training know how drafters signal a strict duty, how exceptions limit it, and which parts of a document bind and which only explain. They can tell a real requirement from a statement of intent. They also know how the same duty can be worded differently across regulations, which helps keep labels consistent.
Specialists write the obligation definitions, set the structure rules, and review hard cases. This reflects Globik AI’s approach of using verified domain experts for work that depends on judgment, where a generalist would be guessing.
Before starting an obligation extraction project, settle these points:
A rule only helps an organization if its duties can be found, understood, and checked. Strong regulatory obligation extraction uses clear definitions of what counts as a duty, careful handling of exceptions and references, honest flags for vague wording, and reviewers with legal training. With that foundation, models can turn long rule text into requirements that teams can act on.
It is the labeling of rule text so AI can find each duty and record who must do what, when, and under which conditions. Annotators follow written definitions built with legal experts.
It is a statement that requires, prohibits, or allows an action. Strong wording such as “must” creates a duty, while softer wording may only advise, so the guide must define each.
An exception limits who must act or when. If it is listed alone, the model may treat the duty as unconditional. Linking keeps the full meaning intact.
Annotators should flag it as needing interpretation instead of forcing a precise requirement. A specialist then reviews it, which keeps invented duties out of the training data.
Specialists know how drafters signal duties and exceptions, and which text is binding. They write clear rules and review doubtful passages.