Many teams plan AI data work like a project with an end date. Collect the data, label it, train the model, ship it. But once a model is live, the need for good data does not end. Real users bring new inputs, product teams keep improving the model, and LLM products keep getting tuned.
At that point, training data stops being a single delivery. It becomes a steady flow. That is the problem AI data pipeline management is built to solve.
A model that works well at launch still has to keep up. Products add features, users ask new kinds of questions, and teams want better results in the next version.
Each round of improvement needs fresh, accurate data. If that data arrives late, inconsistent, or from a different team each time, the model's progress slows down.
Globik's Services page describes this need directly. It lists continuous training data delivery for production AI systems and a real-time annotation pipeline for data-hungry model iteration. It also says the service is built for teams with continuous data needs.
Building one good dataset is a project. Our post on what happens between raw data and training-ready data explains the stages that turn raw data into something a model can learn from.
Running a pipeline means doing that work again and again, on a schedule, while the model is live. New batches arrive. Older data needs to be tracked. Someone has to make sure batch twelve meets the same standard as batch one.
That is a different kind of work. It needs less one-time setup and more steady coordination.
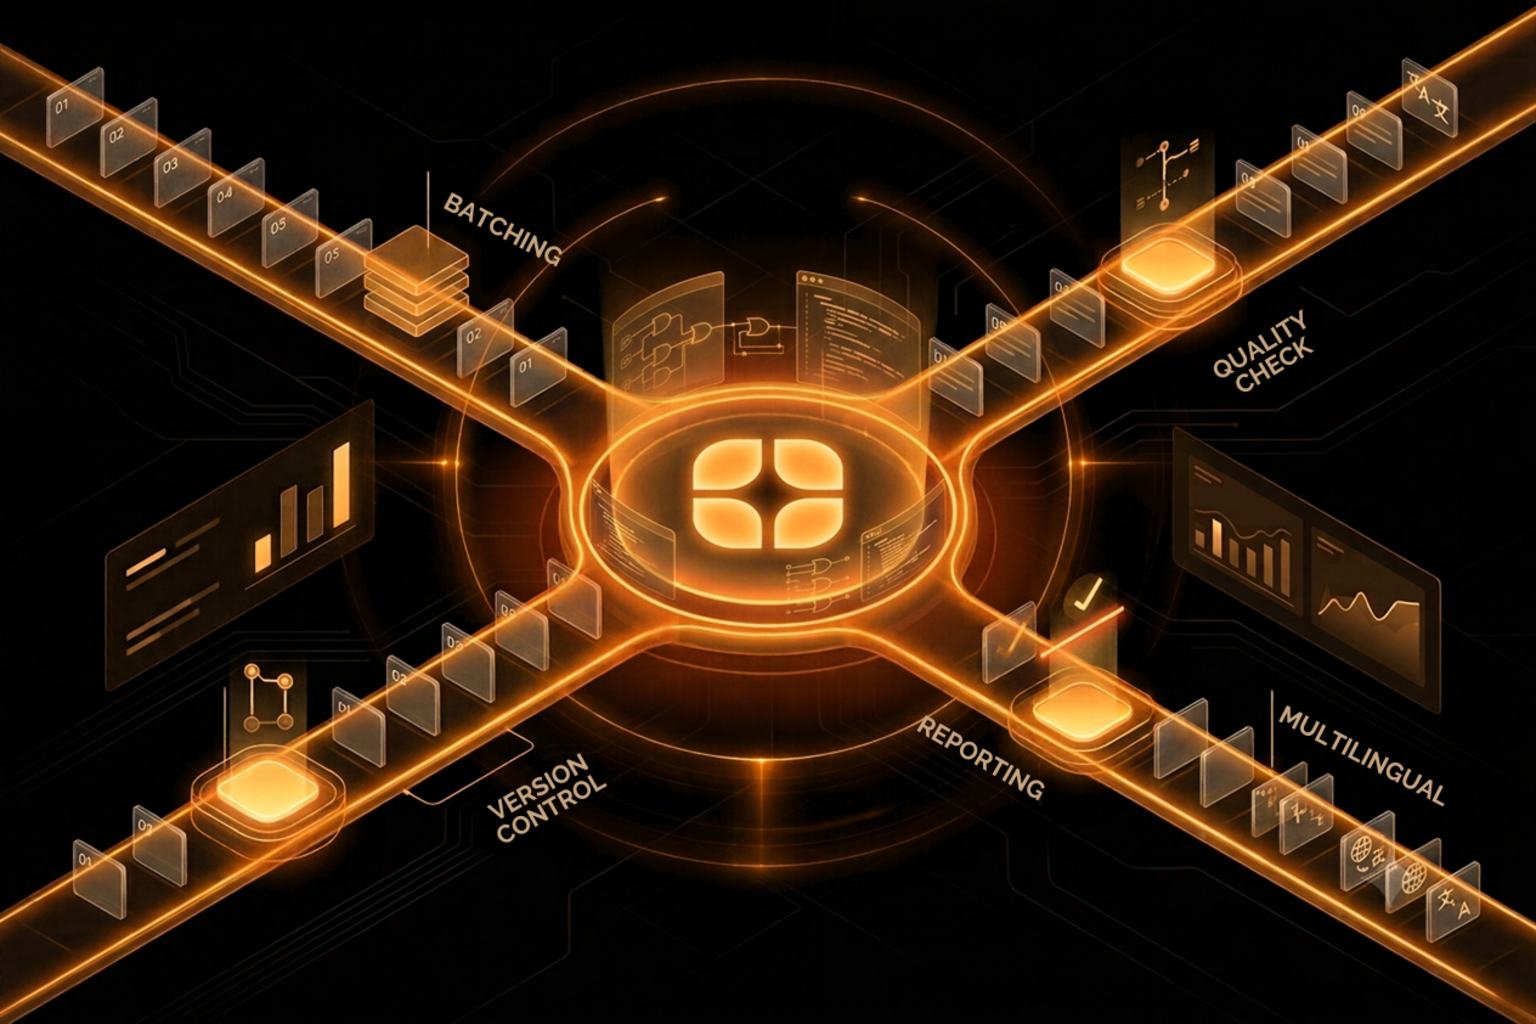
On the Services page, Globik describes this service in plain terms. A dedicated project manager and an expert team are assigned to your data pipeline. They handle:
You also get a single point of contact and regular delivery updates. The page describes it as managed, end-to-end AI data services.
Notice that "quality monitoring" here means keeping an eye on the quality of the data moving through the pipeline. It is about the data, not about tracking how a deployed model behaves.
The Services page names four situations where this service applies.
Continuous training data for production systems: If your model is already live and needs regular new data, a managed flow keeps batches arriving on a schedule instead of being requested from scratch each time.
Ongoing RLHF data for live LLM products: Teams running an LLM product often need new preference labels, instruction-response pairs, and safety annotations on a regular basis. Globik's RLHF service briefs every contributor on your model's use case and quality criteria. Pipeline management keeps that RLHF data coming over time. For more on where this work is heading, read our post on why RLHF isn't just for chatbots anymore.
A real-time annotation pipeline for fast iteration: Some teams retrain often and need labeled data to keep pace. A managed pipeline gives them a steady supply instead of waiting on separate requests.
Managed multilingual operations across markets: Globik annotates in 40+ languages using native speakers, not translators. For a team launching in several regions, one managed pipeline can cover multiple languages without running a separate process for each.
These two items sound technical, but the idea is simple.
Batching means data arrives in clear, planned chunks. Your team knows what is coming and when, so it can plan training runs around it.
Version control means each batch is tracked. When someone asks which data a model was trained on, there is an answer. This becomes more useful the longer a model lives, and the more times it is retrained.
Without both, a data supply tends to turn into a pile of files that nobody fully trusts.
With one-off requests, every new data need starts from scratch. You find a team, explain your guidelines, wait for the work, check the results, and when you need more data later, you often go through the whole thing again, sometimes with a different team that does not know what worked before.
With a dedicated team, one project manager and the same expert team stay with you over time. They already know your guidelines and quality bar from past batches, so you are not re-explaining things each round. Data arrives on a set schedule instead of whenever someone gets to it, and if anything needs to change, you talk to that one point of contact.
The dedicated-team setup does not make the labeling itself easier. It just makes the whole process more predictable.
Globik's Services page names three groups: enterprise AI teams with continuous data needs, product teams scaling annotation operations, and teams that want a managed data partner rather than an internal hire.
If your data needs are a single, fixed project, you may not need ongoing management. But if your model is live and still changing, a steady pipeline is worth considering.
Training data is not something you finish once. For live AI products, it is something you keep supplying. If you want to see how a managed pipeline could fit your product, contact Globik or review the full list of Globik's services.
A. AI data pipeline management is the ongoing handling of a team's training data supply by a dedicated project manager and expert team. It covers batching, delivery scheduling, version control, quality monitoring, and reporting, so new training data keeps arriving in a steady, organized way instead of through one-off projects.
A. Production AI keeps meeting new inputs, new use cases, and new expectations after launch. Fresh, expert-labeled data lets teams keep improving the model instead of freezing it at its first version. Globik supports this with continuous training data delivery for production AI systems and a real-time annotation pipeline for model iteration.
A. Yes. Globik's pipeline management includes ongoing RLHF data generation for live LLM products. Contributors are briefed on your model's use case and quality criteria, and a dedicated project manager and single point of contact oversee batching, version control, and regular delivery updates as your model keeps changing.
A. Yes. Managed multilingual data operations across multiple markets are part of the service. Globik annotates in 40+ languages using native speakers, not translators, so a team expanding into new regions can keep one delivery process while the data covers the languages and dialects each market needs.
A. It suits enterprise AI teams with continuous data needs, product teams scaling annotation operations, and teams that want a managed data partner instead of an internal hire. If your data needs are a single, fixed project, a one-time engagement such as a dataset audit may fit better.