If you ask most people what a data annotator does, they'll picture someone clicking through images or text all day, applying simple labels as fast as possible. For a lot of annotation work, that picture is accurate. But for the kind of data that trains serious AI systems, that picture is also the reason so many models fail in the real world.
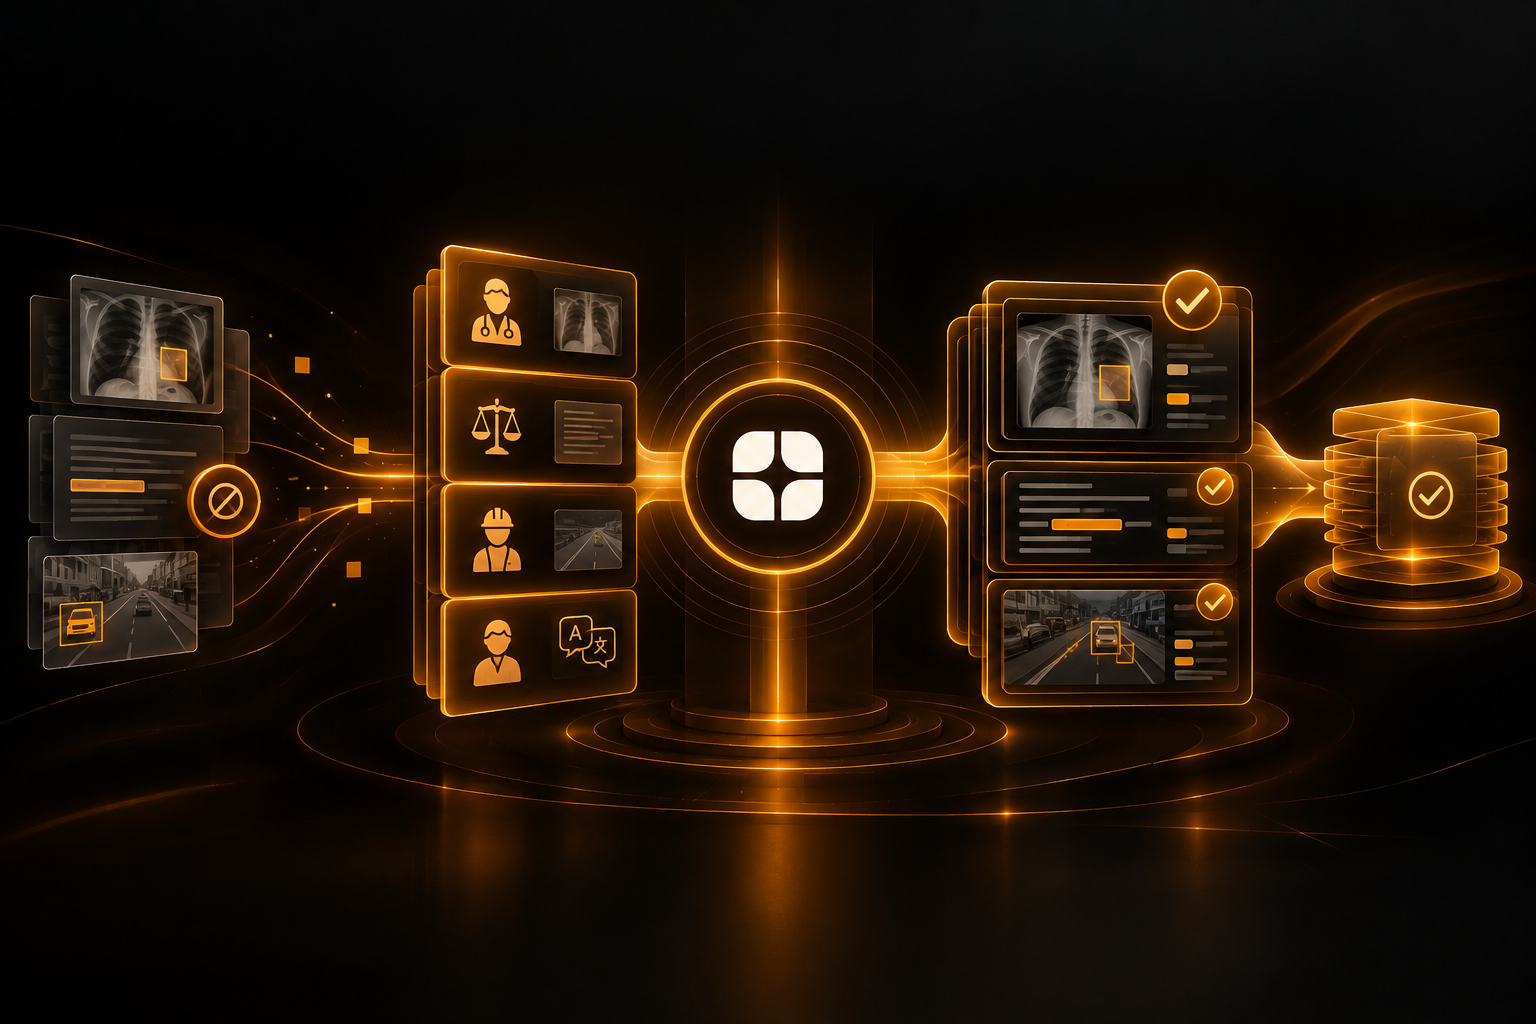
A chest X-ray doesn't just need a label. It needs someone who actually understands what they're looking at. A contract clause doesn't just need a tag. It needs someone who understands what that clause legally means. This is the simple idea behind SME-led annotation: the person labeling the data should understand the data at roughly the same level as the person who will eventually use the model built from it.
This post explains why we built our workforce around domain professionals instead of generic data entry staff, and why that decision shapes almost everything else about how we work.
Generic data labeling works fine for simple, low-stakes tasks. Tagging whether an image contains a cat or a dog doesn't require specialized knowledge. Most people can do it accurately with minimal training.
The problem starts when the data itself requires judgment, not just recognition. A general data entry worker can correctly identify that an X-ray shows "something unusual" in a lung. They usually cannot tell you whether that unusual shape is a harmless scar from an old infection or an early-stage tumor. Those two things might look similar to an untrained eye, but they mean completely different things to a diagnostic model trained on that label.
This is exactly where generic annotation quietly breaks down. The data looks labeled. The label even seems reasonable. But it's wrong in a way that's very hard to catch later, because nobody downstream is checking it against real clinical or legal knowledge.
This is why our workforce isn't built around people trained specifically to label data. It's built around people who already understand a domain deeply, and who are then trained on how to translate that expertise into consistent, usable labels.
Our network includes practicing and licensed doctors, lawyers, engineers, and other domain professionals working as part of our expert workforce. They're not learning the subject matter on the job. They already have it. What they're trained on is how to apply that knowledge consistently within a structured annotation process, how to flag genuine edge cases instead of guessing, and how to document their reasoning so it holds up under review.
This flips the usual order of operations. Instead of teaching annotation workers a little bit about a specialized field, we start with people who already know the field, and build annotation skill on top of that foundation.
The difference this makes isn't abstract. It shows up directly in the quality of the labeled data.
A radiologist labeling medical images understands anatomical context a generalist simply doesn't have. They know which anomalies are clinically significant and which are incidental findings that don't change a diagnosis. A lawyer reviewing contract clauses understands which phrasing creates real legal risk and which is standard boilerplate that looks concerning but isn't. A native-speaking linguist reviewing conversational data understands cultural context and intent that a literal transcription would miss entirely.
This is what it actually means to have domain professionals in AI pipelines, not just as consultants reviewing a sample at the end, but as the people doing the core labeling work itself. The expertise isn't a quality check bolted onto generic labeling. It's built into the data from the first pass.
None of this works if "domain expert" is just a label someone puts on their profile. Before any contributor works on live data, they go through identity and background checks, an AI-led interview that evaluates how they reason through problems, and a domain-specific assessment relevant to their actual field.
This verification step matters because expertise claims are easy to make and hard to confirm without a real process behind them. A verified radiologist and someone who watched a few medical videos online can both describe a chest X-ray in confident language. Only one of them should be labeling data that trains a diagnostic model.
An SME-led annotation workforce is more expensive to build and maintain than a generic labeling pool. Verified professionals command higher rates than general data entry work, and recruiting real doctors, lawyers, and engineers takes more effort than recruiting for a low-skill task.
We've made peace with that trade-off, because the alternative costs more in a different way. A model trained on confidently-wrong labels doesn't just underperform quietly. It fails in front of real users, sometimes in high-stakes situations where the cost of being wrong is measured in more than dollars. Paying more for the right expertise upfront is cheaper than discovering a systemic labeling error after a model is already deployed.
This approach isn't necessary for every type of data. Simple, low-ambiguity tasks don't need a licensed professional behind every label, and applying this level of rigor everywhere would be wasteful.
It matters most in domains where a wrong label carries real consequences: healthcare, legal, finance, and other fields where a model's decision affects a person's health, rights, or financial outcome. In these domains, the question isn't whether expert-led annotation is worth the added cost. It's whether a company can afford the risk of not having it.
This single decision, building around domain professionals instead of generic labor, shapes almost every other part of how we operate. It's why we run domain-specific calibration before scaling any batch. It's why our review process includes peer review from other professionals in the same field, not just general quality scoring. It's why clients working with us on specialized data get matched to people who understand that domain, not whoever happens to be available next.
None of this is about avoiding generalist annotators altogether. It's about matching the level of expertise to the level of risk in the data itself, and being honest about which tasks genuinely need a domain professional behind them.
Generic data entry has a place in AI data work, but it isn't the right foundation for every kind of data, especially data that will shape decisions affecting people's health, legal standing, or financial wellbeing. Building an expert workforce of real domain professionals costs more and moves more deliberately than a generic labeling pool. But it produces data that actually reflects the judgment of the people who understand it best, which is the only kind of data serious AI systems should be trained on.
A: SME-led annotation means data is labeled by subject matter experts, such as doctors, lawyers, or engineers, who already understand the domain deeply, rather than by generalist data entry workers following a simple instruction sheet.
A: Generic data entry is not suitable for specialized data because tasks involving medical, legal, or financial judgment require real domain knowledge to label correctly, and a generalist can apply a label that looks reasonable but is factually or contextually wrong.
A: An expert workforce improves AI model quality by ensuring labels reflect real domain judgment, such as distinguishing a clinically significant finding from an incidental one, which generalist annotators without that background typically cannot do reliably.
A: Domain professionals are typically verified through identity and background checks, an evaluation of their reasoning ability, and a domain-specific skills assessment, ensuring claimed expertise is confirmed before they work on live data.
A: No, not every type of data needs domain professionals in AI pipelines. Simple, low-ambiguity tasks can be handled by generalist annotators, while domain professionals are most necessary for high-stakes fields like healthcare, legal, and finance where incorrect labels carry real consequences.