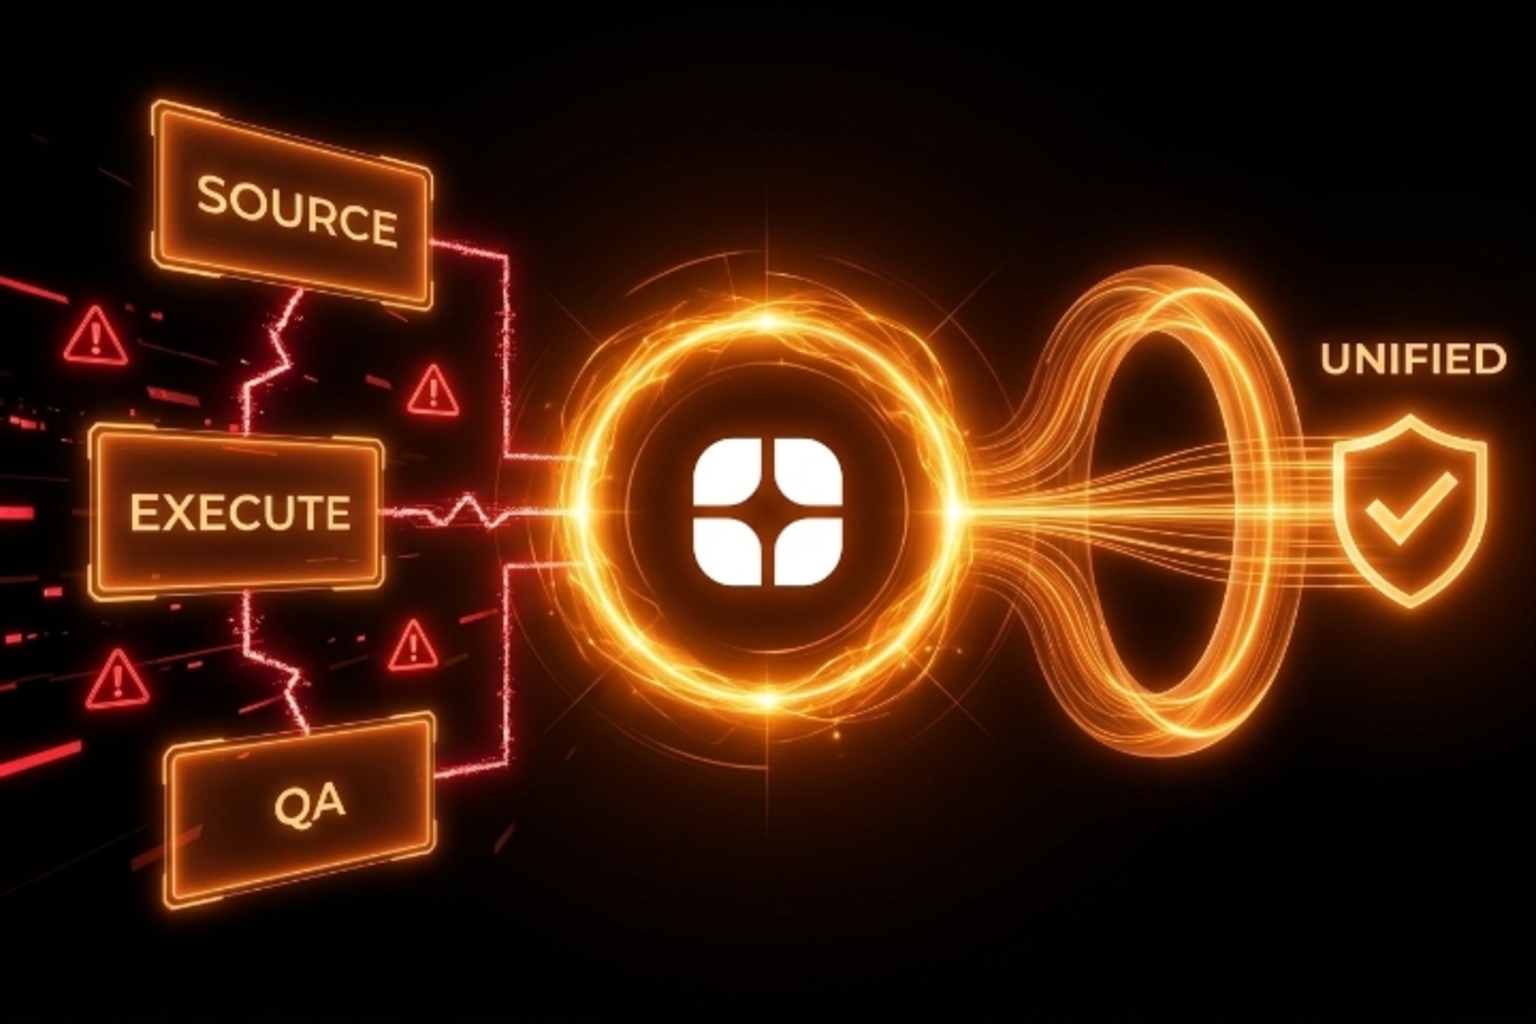
A lot of AI teams build their data pipeline the way they'd build any other piece of infrastructure: pick the best specialist for each piece and assemble them into a system. One vendor sources contributors. Another runs the actual annotation. A third handles quality assurance. Each piece looks reasonable on its own.
The problem shows up in the seams, not the pieces. This post explains why splitting sourcing, execution, and QA across separate vendors creates risk that's easy to miss upfront, and why an end-to-end AI data partner often outperforms a three-vendor setup, even when each individual vendor is competent.
This fragmented setup usually isn't a deliberate strategy. It happens gradually: sourcing gets outsourced first because finding and vetting contributors feels like a specialized problem on its own, execution ends up with whichever team already has the right tooling, and QA gets bolted on later, often brought in only after quality issues have already surfaced elsewhere.
Each decision makes sense in isolation. The result: three vendors who've never spoken to each other, managing different pieces of the same pipeline, usually isn't something anyone planned from the start.
Splitting sourcing, execution, and QA creates a specific, recurring set of failure points:
None of these problems come from any single vendor doing bad work. They come from the gaps between vendors that nobody is specifically responsible for closing.
A unified data pipeline, where sourcing, execution, and QA sit under one accountable team, removes the structural cause of these problems rather than just treating the symptoms. Feedback loops stay internal, since a QA reviewer flagging a pattern reaches the people doing sourcing and execution directly, often the same day, instead of traveling through three separate company processes.
Guidelines also stay consistent by default, since one team interpreting one rubric removes the drift that happens when execution and QA are run by companies with different internal interpretations. And accountability has nowhere to hide when quality drops; there's one team to ask why, not three companies pointing at each other.
This isn't about Globik being connected to hybrid human-AI workflows in name only; it reflects the same shift already happening industry-wide toward treating annotation as one connected process rather than an isolated task handed between parties.
Running sourcing, execution, and QA as one connected system is harder to build than simply contracting out each piece separately. A provider genuinely set up this way typically needs:
This is a meaningfully different operating model than stitching together three specialist vendors, even when each of those three vendors is genuinely good at their specific piece.
For a team evaluating a potential data partner, a few direct questions separate a genuinely integrated pipeline from three vendors loosely bundled under one sales pitch: If a QA reviewer flags a recurring issue, who do they report it to, and how quickly does that reach the people doing the actual labeling? Are the same guidelines used by both the execution team and the QA team, or maintained separately? Is there one accountable point of contact for the full pipeline, or separate contacts for sourcing, execution, and QA? And if quality drops, who is actually responsible for fixing it, not just reporting it?
Splitting sourcing, execution, and QA across three vendors feels like specialization, but it often just relocates risk into the gaps between them, gaps nobody is specifically accountable for closing. An end-to-end AI data partner, running sourcing, execution, and QA as a genuinely unified data pipeline through a real annotation execution layer, removes those gaps structurally rather than trying to manage around them after the fact. The question worth asking isn't whether each vendor is good at their piece. It's who owns the seams between them.
A: AI teams often end up with separate vendors because sourcing, execution, and QA get added to the pipeline at different times, usually as specific problems arise, rather than being planned as one connected system from the start.
A: Common problems include unclear ownership when quality issues arise, feedback that doesn't reach the right team quickly, inconsistent interpretation of guidelines between vendors, and delays caused by handoffs at each vendor boundary.
A: A unified data pipeline is a setup where sourcing, execution, and quality assurance are managed by one accountable team rather than separate vendors, allowing feedback, guidelines, and accountability to stay consistent across the entire process.
A: An end-to-end AI data partner provides a verified contributor network, execution workflows built around that same pool, continuous quality assurance integrated into the pipeline, and a single point of accountability for the full process.
A: A company can ask whether QA feedback reaches the execution team directly, whether guidelines are shared across functions, and whether there is one accountable contact for the entire pipeline rather than separate contacts for each stage.
A: Not necessarily. While a unified pipeline may look like a bigger upfront commitment, it typically reduces the hidden costs of rework, miscommunication, and delays that come from coordinating separate vendors, which often outweigh any short-term savings from picking individual specialists.
A: Yes, though it typically works best by first running a smaller-scoped phase with the new unified partner to validate quality and fit, before fully transitioning away from the existing separate vendors for sourcing, execution, and QA.