A few years ago, "data vendor" meant one thing: a company you sent files to, and they sent labeled files back. Simple transaction, simple relationship. That model is already breaking down, and by 2027, it will look almost unrecognizable.
The reason isn't hype. It's structural. As AI models move from experiments into real products, the work of preparing data for them has become too complex, too specialized, and too tied to business outcomes to stay a simple vendor task. What's replacing it looks less like outsourcing and more like consulting.
This post looks at why data annotation vendor evolution is happening, what's driving it, and what it means for how companies should think about their AI data strategy going forward. It's also, quietly, a description of where companies like Globik already operate.
The traditional data vendor model worked well when the ask was simple: label these images, transcribe this audio, tag this text. A company could define the task clearly, hand it off, and expect consistent output.
That model assumes the hardest part of the work is execution. But for most serious AI projects today, the hardest part isn't execution. It's deciding what to label, how to label it, which edge cases matter, and how the labeled data connects to the business outcome the model is supposed to support.
A vendor that only executes instructions can't help with any of that. And a company that has to figure all of that out on its own, before even contacting a vendor, ends up doing a huge amount of strategic work internally, then handing over only the "easy" part.
This gap is exactly why the vendor model is shifting.
When people hear "consultancy," they often think of expensive advice with no real deliverable. That's not what's happening here. The shift is more specific than that.
Data vendors are increasingly being asked to:
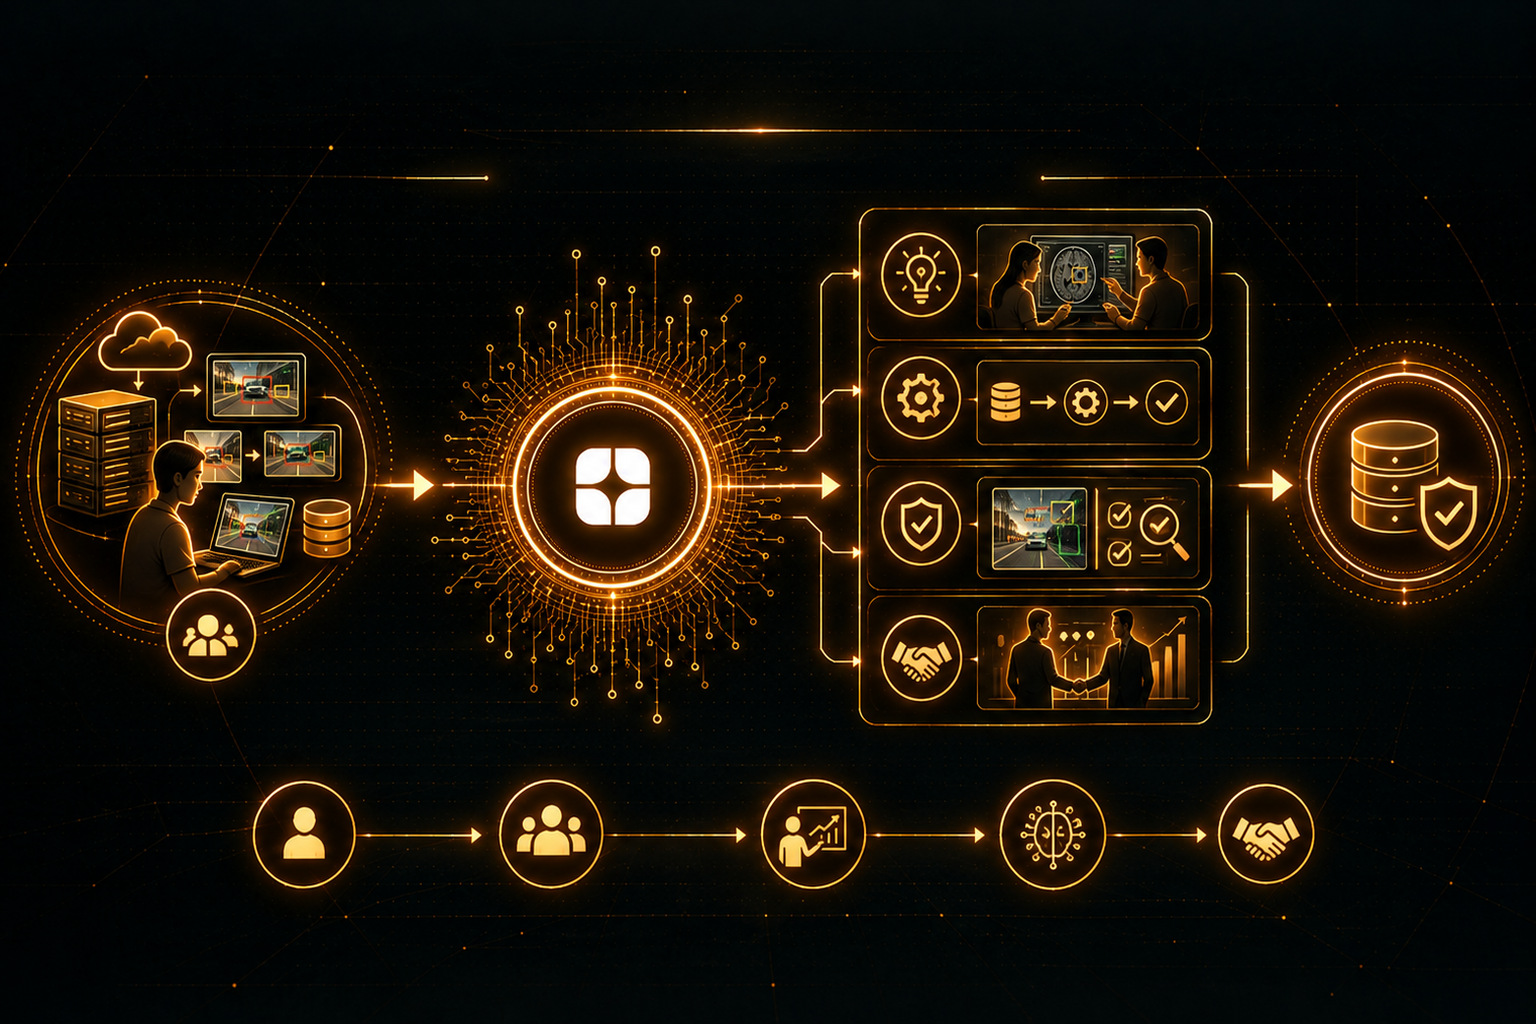
This is functionally a managed data services relationship, even if the deliverable is still labeled data at the end. It's also, structurally, closer to how a handful of providers are already choosing to operate. Globik's own engagement model, for example, moves from a short discovery call into a scoped phase, then into what it calls a standing partnership, the same team staying on as new domains and data types get added, rather than a new vendor relationship starting from zero each time.
Three forces are driving this change at the same time.
First, AI use cases have gotten more specialized: Early machine learning projects often used general datasets. Now, companies are training models for narrow, high-stakes tasks, medical diagnosis support, legal document review, financial fraud detection, where generic labeling knowledge isn't enough. This requires real domain understanding, not just labeling speed. This is part of why domain-specific verification, radiologists reviewing medical data, lawyers reviewing contracts, native speakers handling multilingual audio, has become a baseline expectation rather than a premium add-on.
Second, data quality problems have become visible at the business level: A few years ago, a poorly labeled dataset was mostly an internal engineering headache. Now, it shows up as a model making bad decisions in front of customers, regulators, or investors. That visibility pushes data quality conversations up to leadership, and leadership wants advisors, not just task executors.
Third, companies don't want to build in-house data expertise from scratch: Hiring a team that understands both AI pipelines and a specific domain, healthcare, legal, finance, is slow and expensive. It's far more practical to bring in a partner who already has that expertise, and who can guide strategy as well as deliver the work.
Put together, these three forces are pushing managed data services to look a lot more like an extension of a company's own strategy team, and a lot less like an outsourced task queue.
If this shift is real, and the direction strongly suggests it is, then the way companies evaluate data vendors needs to change too.
Instead of asking "how fast can you label this," the more useful questions become:
Companies that keep evaluating vendors purely on price-per-label will increasingly find themselves working with partners who can't keep up with the complexity of what they actually need. Companies that shift toward evaluating strategic fit will end up with partners who function more like an embedded team than an external vendor, closer to what a scoped-phase-to-partnership model already looks like in practice.
You don't need to wait until 2027 to start adjusting how you work with data partners. A few practical steps help now:
The line between "data vendor" and "data strategy partner" is already blurring, and by 2027, it will be hard to tell the difference. Companies that treat this shift seriously, and choose partners who can operate as an extension of their own strategy, not just a task queue, will be better positioned as their AI systems move into higher-stakes, more specialized territory. The vendors that survive this shift won't be the fastest or cheapest. They'll be the ones who already function less like a supplier and more like a consultancy that happens to deliver data, a model some providers, including Globik, are structured closer to today than the traditional vendor approach.
A: Data annotation vendor evolution refers to the shift where data labeling providers move beyond simple task execution into strategic roles, helping define labeling approaches, advise on quality standards, and support long-term AI data strategy rather than just delivering labeled files.
A: AI data vendors are looking more like consultancies because AI use cases have become more specialized, data quality issues now affect business outcomes directly, and companies prefer partners who bring domain expertise and strategic input rather than building that expertise in-house.
A: A traditional data vendor executes a defined labeling task and delivers output. Managed data services involve an ongoing relationship where the provider helps design the data pipeline, advises on quality standards, and stays engaged as the AI project evolves, similar to a scoped-phase-to-partnership model.
A: Companies should evaluate a data partner by their domain expertise, willingness to advise on the AI data strategy itself, ability to design pipelines rather than just execute instructions, and whether they offer an ongoing relationship instead of one-off project work.
A: This shift is already underway and is expected to become the mainstream model by 2027, driven by the growing specialization of AI use cases and the rising business impact of data quality decisions.
A: A company can prepare its AI data strategy by involving data partners earlier in the problem-definition stage, asking directly about relevant domain expertise, favoring ongoing engagement models over one-off batches, and paying attention to whether a vendor offers real advice rather than simply executing instructions.