Most conversations about AI training data start with the assumption that the data doesn't exist yet. But a large number of teams are sitting in a different situation entirely: they already have a labeled dataset, built in-house, inherited from a previous vendor, or assembled over several projects, and they genuinely don't know whether it's good. The model isn't performing the way it should, and nobody can say for certain if the problem is the architecture or the data underneath it.
This is where a dataset audit comes in. Rather than starting a new labeling project, a dataset audit takes data a team already has and answers one specific question: can this be trusted, and if not, what needs to change before anyone trains on it again?
A dataset audit is not the same engagement as building a dataset from scratch, and the two get confused more often than they should. Three situations tend to trigger the need for one specifically.
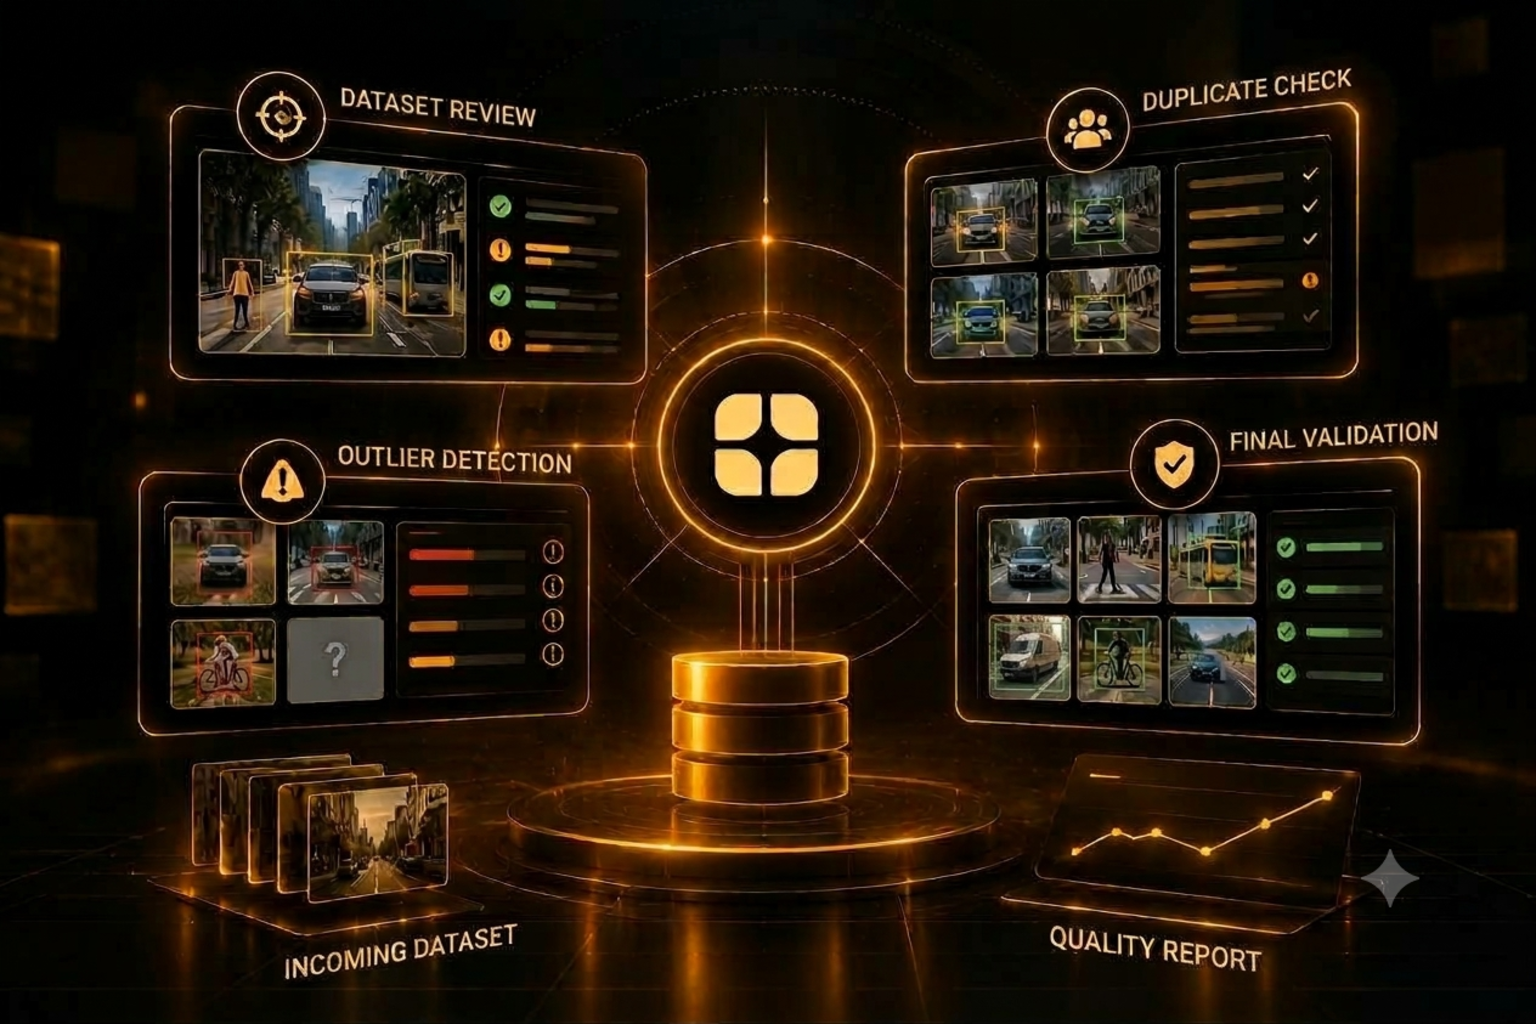
A dataset audit isn't a single pass or a quick glance at a sample. It's a structured review built to surface exactly where a dataset is strong and where it isn't.
Once the problem areas are identified, the next step is targeted correction, not a full relabel of everything. Flagged batches, the specific items and categories found to be inconsistent or inaccurate go through re-annotation by qualified reviewers who understand what the correct standard should have been in the first place.
This matters because full relabeling is expensive and usually unnecessary. In most datasets we've audited, the actual problems cluster in a specific subset, certain categories, certain time periods, certain annotators, rather than being spread evenly across everything. Fixing that subset, rather than redoing the entire dataset from zero, is both faster and a far better use of budget.
It also matters for a less obvious reason: a full relabel throws away the parts of the dataset that were already correct, which means paying twice for work that didn't need to be redone in the first place. Targeted re-annotation keeps the good portions of the dataset intact and puts the budget specifically toward the segments that actually needed attention, which is usually a fraction of the total volume.
A dataset audit closes with a written report, and this is often the part that matters most to a team making a decision about whether to trust, fix, or discard what they have.
The report typically includes:
For teams comparing vendors, this report also functions as a vendor comparison benchmark, giving a factual basis for evaluating whether a previous labeling partner actually delivered what was promised.
A dataset audit makes the most sense for a specific set of situations: teams with an existing dataset that has never been independently validated, teams in the middle of switching away from a previous vendor and inheriting data they didn't produce themselves, and teams whose models are underperforming despite having a fully labeled dataset already in hand. In each case, the common thread is the same: there's labeled data, but no confidence in it yet.
Globik AI treats a dataset audit the same way it treats any annotation engagement: with verified domain experts reviewing the data, not a generic pass-fail script. The process starts with understanding the domain and what "correct" actually looks like for that specific use case, then moves through accuracy checks, consistency analysis, and targeted re-annotation of flagged items, before delivering the written report with clear next steps.
This is also why a short discovery conversation is the right starting point rather than committing to a full audit blind. A 30-minute call is enough to understand the dataset, the suspected problem areas, and what a useful outcome would look like, before any larger engagement begins. From there, the audit itself typically runs as a scoped, time-bound engagement rather than an open-ended review, so a team knows upfront roughly how long it will take to get a clear answer about their data.
A model is only as reliable as the data underneath it, and for teams holding a dataset they can't fully vouch for, that uncertainty doesn't go away on its own. A dataset audit turns a vague worry, "is our data actually good," into a specific, documented answer, along with a fixed dataset where it matters. If that uncertainty sounds familiar, a short scoping conversation is a low-effort way to find out exactly where things stand.
A dataset audit is a structured review of a labeled dataset a team already has, checking its accuracy, consistency, and overall usability before it's used to train or retrain a model. It's distinct from a new labeling project, since the data already exists and the goal is validation and correction rather than creation.
Common triggers include a model underperforming despite having labeled data, switching away from a previous annotation vendor and inheriting their work, or having a dataset that grew over time without ever being formally validated.
Flagged items and categories go through re-annotation by qualified reviewers, rather than a full relabel of the entire dataset. Most quality problems cluster in specific segments, so targeted correction is usually faster and more cost-effective than starting over.
It typically includes an overall quality summary broken down by category, specific problem areas with concrete examples, a record of what was corrected through re-annotation, and recommendations for preventing similar issues in future labeling work.
Yes. Because the audit independently assesses what was actually delivered, it gives teams a factual basis for comparing vendors or deciding whether a prior vendor's work is usable, rather than relying on assumptions.