Most people think data labeling is simple. Look at a piece of data, pick the right label, move to the next one. But if that were true, every AI model trained on labeled data would work equally well. It doesn't.
The real difference isn't the label. It's whether the person labeling the data actually understands why that label matters to the person who will use the model later. A doctor reading a scan, a lawyer reading a contract, a driver relying on a self-driving car - they all need the model to get it right in a very specific way. Getting an annotator to think like that person is the real job of annotator training.
This post explains how we approach that at Globik, and why it matters more than most teams expect.
Imagine two annotators labeling the same medical scan. One simply follows a checklist: mark the shape, choose a category, move on. The other pauses and asks, "If a radiologist saw this label, would it help them make a faster, safer decision?"
Both annotators might technically follow the same instructions. But only one of them is actually thinking about the outcome the label is meant to support. That's the gap between a person who labels data and a person who understands the model's real job.
This is exactly why generic, one-size-fits-all annotation often produces models that look fine in testing but fail in real use. The labels were technically correct, but they weren't shaped around how the end user actually needs the information.
A strong contributor onboarding process doesn't begin with training videos or a welcome email. It begins with verification.
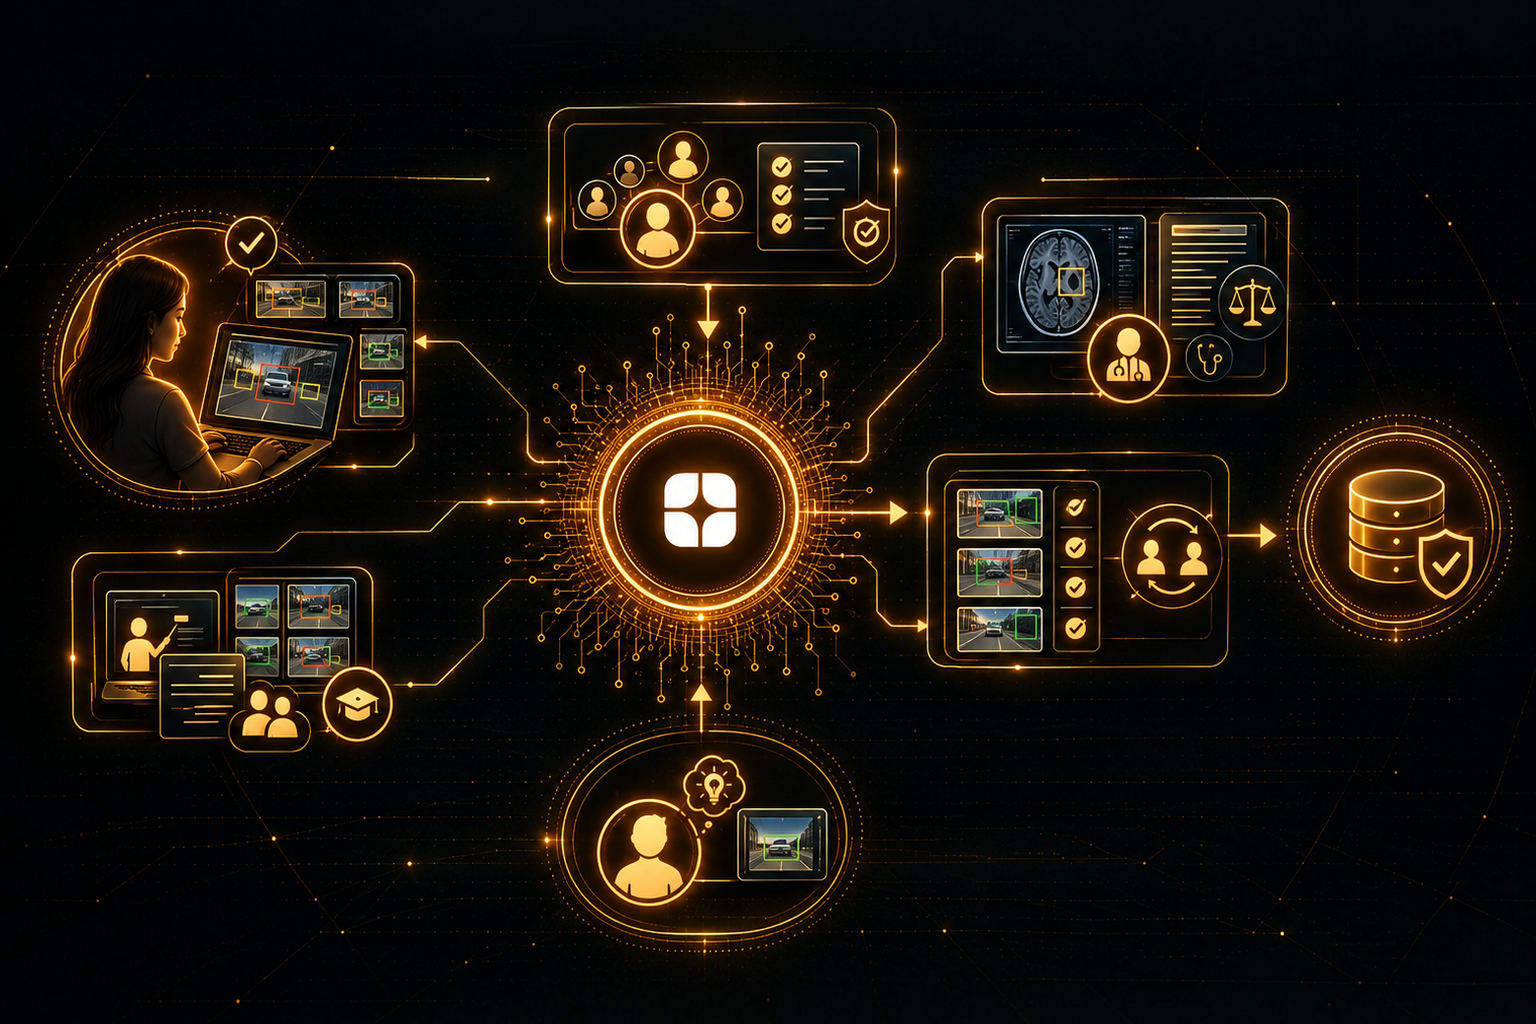
Before any contributor works on live data, they go through identity and background checks, an AI-led interview that scores how they think and explain their reasoning, and a domain-specific test related to the field they'll be working in. Only after clearing these steps do they move into training on the actual project.
This matters because training only works if the person receiving it already has the right background. You can teach someone the rules of a task, but you can't teach real domain judgement in a single afternoon. A radiologist already understands anatomy. A lawyer already understands contract language. Contributor onboarding builds on top of that existing expertise, instead of trying to create it from scratch.
Once a contributor is verified, the actual annotator training is shaped around the specific project, not a one-size-fits-all annotation course. This usually includes:
This is what separates real training from a quick instructions document. The goal isn't just teaching someone to follow steps. It's building an understanding of why those steps exist.
None of this works as a one-time event. A quality-first workforce is built through repetition, feedback, and accountability, not a single onboarding session.
After training, contributors don't work in isolation. Every batch goes through multi-layer quality checks, and feedback flows back to the annotator, not just into a report no one reads. Over time, this creates a workforce where people aren't just labeling data correctly. They're building a habit of thinking about outcomes, not just tasks.
This is also why reputation and quality scores matter. Contributors who consistently understand the end-user perspective get matched to more advanced, higher-trust projects. It rewards judgement, not just speed.
You don't need a large team or a complex system to start applying this approach. Most teams can improve their own annotator training with four simple steps.
None of these steps require expensive tools. They require treating training as an ongoing part of the work, not a one-time task completed before the "real" labeling begins.
As AI models move from experiments into real healthcare, legal, and financial decisions, the cost of a poorly trained annotator gets higher. A mislabeled image in a casual app is a minor bug. A mislabeled medical scan used to train a diagnostic model is a completely different kind of risk.
This is exactly why annotator training can't be treated as a formality. It's not a box to check before the "real work" begins. It is the real work. The quality of the end model depends directly on whether the people labeling the data understood who they were really labeling it for.
Good annotation isn't about labeling data quickly. It's about labeling it the way the model's actual end user would need it to be labeled. That only happens when contributor onboarding starts with real verification, training is built around the specific domain, and every contributor understands the outcome their work supports. This is what builds a genuinely quality-first workforce, one that doesn't just follow instructions, but understands why those instructions exist in the first place.
A: Thinking like the end user means an annotator considers how their label will actually be used by the person relying on the model, such as a doctor or a lawyer, instead of simply following a checklist without understanding the purpose behind it.
A: Contributor onboarding is the process of verifying and preparing an annotator before they work on real data, including identity and background checks, an AI-led interview, and a domain-specific skills test, followed by training built around the actual project.
A: Annotator training needs to be domain-specific because generic instructions don't teach real judgement in a specialized field. Domain-specific training uses real examples and rubrics from that field, helping annotators understand why an answer matters, not just what answer to choose.
A: A quality-first workforce is built through ongoing feedback, multi-layer quality checks, and accountability after training, not a one-time onboarding session. This rewards annotators for good judgement and consistency, not just speed.
A: Annotator training matters more for high-stakes AI models because mistakes in fields like healthcare, legal, or finance carry real consequences. Poorly trained annotators can introduce errors that are difficult to catch later and can directly affect model reliability in serious use cases.