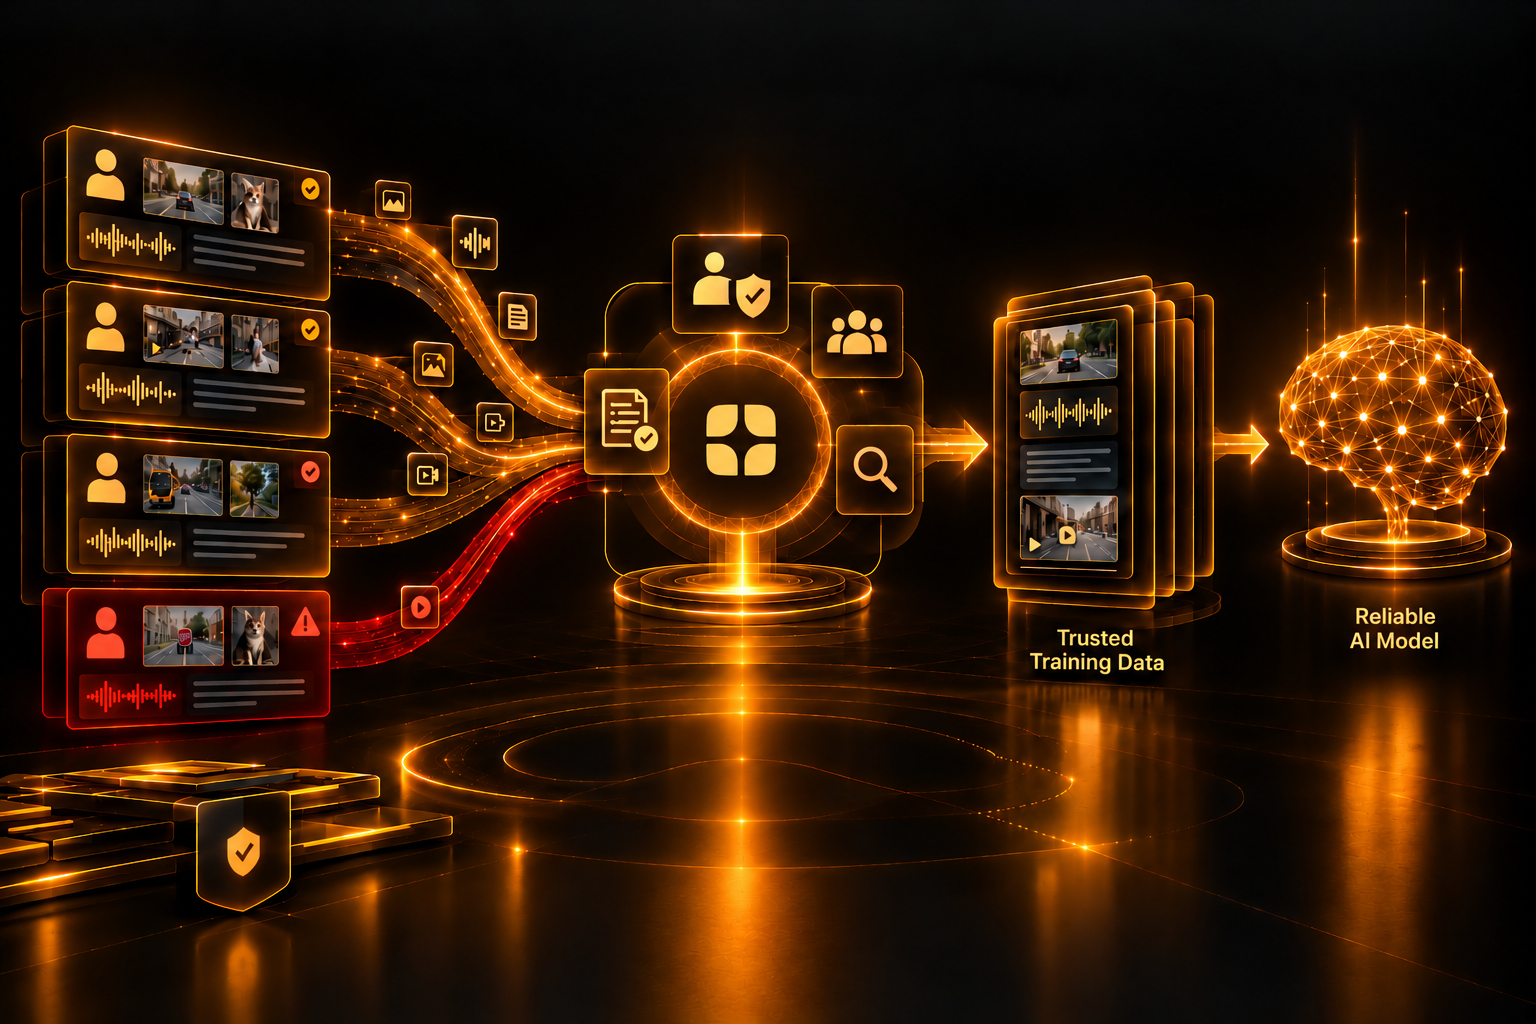
When people talk about data poisoning, the conversation usually goes straight to technical defenses: detection algorithms, anomaly scoring, adversarial robustness testing. All of that matters. But a lot of poisoned data never gets caught by any of it, because it never looked like an attack in the first place. It looked like a normal batch of labeled data from a normal vendor.
This is the part of the conversation that gets skipped. Data poisoning isn't only a technical problem to engineer around after the fact. It's also a question of who had access to your training pipeline before the engineering even started. This post looks at why vendor due diligence deserves a seat at the same table as technical security controls, not a separate, lower-priority conversation.
Data poisoning sounds dramatic, but in practice it's often quiet and easy to miss. It can mean deliberately mislabeled examples inserted into a training set, subtle patterns designed to create a backdoor in a model's behavior, or biased labeling introduced gradually enough that it doesn't trigger obvious quality alerts.
The unsettling part is that poisoned data frequently looks fine on the surface. A mislabeled example doesn't come with a warning sign attached. It looks like one of thousands of normal labels, sitting in a batch that otherwise passes every standard quality check. By the time its effect on model behavior becomes visible, the data has often already been fully absorbed into training.
Most AI security conversations focus on what happens after data arrives: scanning it, validating it, testing the model trained on it. Far fewer conversations focus on where the data came from in the first place, and who could introduce a problem into it.
This matters because training data usually passes through people before it reaches a model: annotators, reviewers, and whoever manages that annotation process. If that group includes individuals who weren't properly vetted, or if the vendor managing them has weak internal controls, the opportunity for poisoning exists long before any technical detection system gets a chance to catch it. Treating data poisoning purely as a downstream security issue misses the fact that the earliest, most effective point of prevention is deciding who gets access to the pipeline at all.
A lot of vendor evaluation processes focus on cost, turnaround time, and general quality metrics. Few ask the specific questions that would reveal whether a vendor's internal controls could actually prevent a bad actor from quietly introducing poisoned labels.
Weak due diligence often shows up as a few recognizable patterns:
None of these gaps require sophisticated hacking to exploit. They just require a vendor relationship that was never evaluated closely enough to notice them.
Technical safeguards, like statistical outlier detection or model behavior testing, are genuinely useful and should absolutely be part of any serious approach to data poisoning. But they share a common weakness: they're built to catch problems after the data already exists.
A well-executed poisoning attempt is often specifically designed to avoid tripping these detections, subtle enough to blend into normal variation, distributed across enough examples that no single outlier stands out. Relying entirely on downstream detection means betting that every poisoning attempt will be sloppy enough to get caught. That's not a safe assumption for any team serious about AI security.
Vendor-level prevention works differently. Instead of trying to catch a problem after it's already in the data, it reduces the chance that an unverified or unaccountable person had the opportunity to create the problem in the first place.
For teams serious about reducing data poisoning risk at the source, a few practical questions matter more than a vendor's marketing claims:
None of these questions require specialized security expertise to ask. They require treating vendor selection as part of the security conversation, not a separate procurement decision made before security gets involved.
As AI systems take on higher-stakes roles- fraud detection, medical decision support, autonomous systems the cost of undetected data poisoning rises sharply. A subtle bias or backdoor introduced early in training can be extremely difficult to fully remove once a model is deployed and already trusted in production.
This is exactly why vendor due diligence can't be treated as a one-time checkbox during procurement. It needs to be an ongoing part of how a company evaluates and maintains its data supply chain, the same way security teams continuously monitor technical infrastructure rather than reviewing it once and moving on.
Data poisoning is a real technical threat, and technical defenses matter. But treating it purely as an engineering problem overlooks where a lot of the actual risk originates: in who was allowed to touch the training pipeline before any detection system had a chance to intervene. Strong vendor due diligence, verified contributors, traceable accountability, and real oversight, close a door that technical defenses can only ever try to catch someone walking back out of. For any team serious about AI security, vendor selection deserves to be treated as a security decision, not a separate conversation that happens before security gets involved.
A: No, data poisoning is not only a technical security issue. It is also a vendor selection issue, since poisoned data is often introduced by unverified or poorly managed contributors before any technical detection system has a chance to catch it.
A: Weak vendor due diligence often includes a lack of identity verification for contributors, no access segmentation, no traceable link between labels and the individuals who created them, and high contributor turnover with minimal oversight.
A: Technical defenses alone aren't enough because they are designed to catch problems after poisoned data already exists, while a well-executed poisoning attempt is often specifically designed to avoid detection by blending into normal data variation.
A: Companies should ask whether contributors are identity-verified, whetherlabels can be traced back toindividuals, whether access is segmented to limit any single contributmuch poisoned data never gets caught by any of itor's influence, and how the vendor handles unusual or concerning contribution patterns.
A: Data poisoning risk increases in higher-stakes applications because biases or backdoors introduced early in training can be difficult to fully remove once a model is deployed, making prevention at the vendor level more critical than relying on detection after deployment.